
Once a line has been fitted, the next question is how well it fits. The residuals answer that for each observation, but they are in the units of y: a typical miss of 0.7 means one thing for hourly pay in pounds and another for GDP in billions. R-squared puts the fit on a common scale. It compares the fitted line with the crudest prediction available, which is to ignore x and predict the mean of y for everyone, and reports the share of the variation around that mean which the regression accounts for. It is 0 if the line does no better than the mean and 1 if every point lies on the line.
1. What R-squared measures: the line against the mean
Take the five workers from the OLS explainer: years of education after 16 are 0, 1, 2, 3, 4 and hourly pay is £10, 12, 13, 16, 19. Suppose we had to predict each worker's pay without knowing their education. The best single guess, in the sense of the smallest sum of squared misses, is the mean, £14. It misses the five workers by -4, -2, -1, +2 and +5 pounds. Square the misses and add them: 16 + 4 + 1 + 4 + 25 = 50.
Now use education. The least-squares line is 9.6 + 2.2x, and it misses the five workers by 0.4, 0.2, -1.0, -0.2 and 0.6 pounds. The squares add to 1.60.
Knowing education has cut the sum of squared misses from 50 to 1.60. The line has removed 48.4 of the 50, and R-squared is that share:
$$ R^2 = \frac{50 - 1.60}{50} = \frac{48.4}{50} = 0.968 . $$So an R-squared of 0.968 says that the line accounts for 96.8% of the variation in pay around its mean, where variation is measured by squared distances. That is all R-squared is: a comparison between the misses of the fitted line and the misses of the mean.
What students say
“Nicky is an excellent econometrics tutor. He explains complex concepts clearly and makes them much easier to understand.”
“I was completely lost in my economics class, and then I started working Nicky and he totally saved me. He was excellent at explaining the material and extremely accommodating to meet with me many times despite us being in different time zones! Highly recommend working with Nicky!”
“Nicky is a very good and thorough teacher. He has excellent knowledge of econometrics and takes the time to work through your questions. Highly recommended!”
“Really great tutor! Encouraging, knowledgeable, friendly”
“Very good lesson, Nicky is very helpful.”
“Very helpful and clear.”
“I gather it was very useful, thank you!”
“Fantastic!”
2. What are TSS, ESS and RSS?
The three numbers in that calculation have names. Write \(\bar y\) for the mean of y and \(\hat y_i\) for the fitted value of observation \(i\). Each observation's distance from the mean splits into two parts, the part the line accounts for and the residual:
$$ y_i - \bar y \;=\; (\hat y_i - \bar y) \;+\; (y_i - \hat y_i) . $$In words: distance from the mean = explained part + residual.
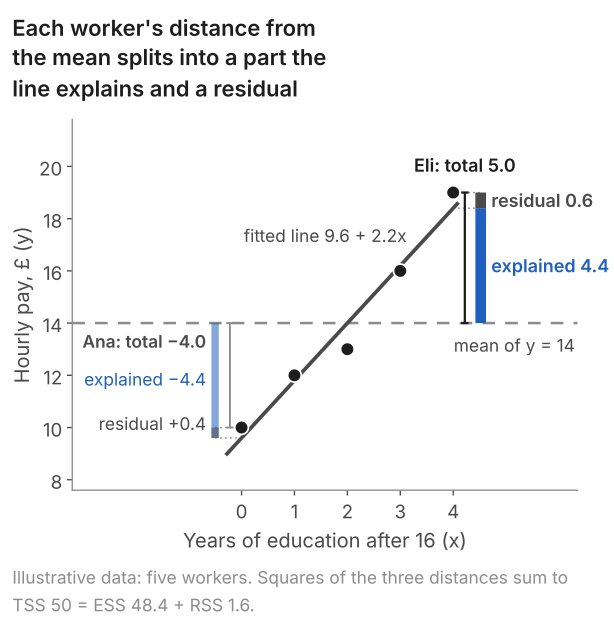
Eli is paid £19, which is £5 above the mean. The line predicts £18.40 for someone with his education, so it accounts for £4.40 of the £5, and the remaining £0.60 is his residual. Square each of the three distances for every worker and add them up:
| Worker | y | Fitted | (y - mean)2 | (fitted - mean)2 | (y - fitted)2 |
|---|---|---|---|---|---|
| Ana | 10 | 9.6 | 16 | 19.36 | 0.16 |
| Ben | 12 | 11.8 | 4 | 4.84 | 0.04 |
| Cara | 13 | 14.0 | 1 | 0.00 | 1.00 |
| Dev | 16 | 16.2 | 4 | 4.84 | 0.04 |
| Eli | 19 | 18.4 | 25 | 19.36 | 0.36 |
| Sum | 70 | 70.0 | TSS = 50 | ESS = 48.4 | RSS = 1.60 |
- TSS, the total sum of squares, \(\sum (y_i - \bar y)^2\): the variation in y to be accounted for. It is what the mean-only prediction gets wrong.
- ESS, the explained sum of squares, \(\sum (\hat y_i - \bar y)^2\): the variation in the fitted values.
- RSS, the residual sum of squares, \(\sum (y_i - \hat y_i)^2\): what is left over. This is the quantity least squares makes as small as possible.
Squaring a sum normally leaves a cross term. For a least-squares line the cross term is zero: the residuals add to zero and are uncorrelated with x (the two conditions that define the line), and the fitted values are a straight-line function of x, so the residuals are uncorrelated with the fitted values as well. Hence the squares add up in the same way as the distances, TSS = ESS + RSS, here 50 = 48.4 + 1.60, in any OLS regression that includes an intercept. R-squared can then be written in two equivalent ways:
$$ R^2 = \frac{\text{ESS}}{\text{TSS}} = 1 - \frac{\text{RSS}}{\text{TSS}} . $$With one explanatory variable, R-squared is also the square of the correlation between x and y. Each fitted value differs from the mean by the slope times the x deviation, so ESS is the slope squared times the sum of squared x deviations; dividing by TSS leaves the squared sum of products over the product of the two sums of squares, which is the squared correlation. For the five workers the correlation is \(22/\sqrt{10 \times 50} = 0.984\), and 0.9842 = 0.968.
The table gives the four quantities for the five workers. Each program reports them in its own layout.
| Quantity | Value |
|---|---|
| Total sum of squares, TSS | 50 |
| Explained sum of squares, ESS | 48.4 |
| Residual sum of squares, RSS | 1.6 |
| R-squared | 0.968 |
Stata: the code
clear
input educ16 pay
0 10
1 12
2 13
3 16
4 19
end
regress pay educ16
Stata: what it prints
. regress pay educ16

      Source |       SS           df       MS      Number of obs   =         5
-------------+----------------------------------   F(1, 3)         =     90.75
       Model |        48.4         1        48.4   Prob > F        =    0.0025
    Residual |         1.6         3  .533333333   R-squared       =    0.9680
-------------+----------------------------------   Adj R-squared   =    0.9573
       Total |          50         4        12.5   Root MSE        =     .7303

------------------------------------------------------------------------------
         pay | Coefficient  Std. err.      t    P>|t|     [95% conf. interval]
-------------+----------------------------------------------------------------
      educ16 |        2.2   .2309401     9.53   0.002     1.465046    2.934954
       _cons |        9.6   .5656854    16.97   0.000     7.799737    11.40026
------------------------------------------------------------------------------
R: the code
# five made-up workers: years of education after 16 and hourly pay in pounds
workers <- data.frame(educ16 = c(0, 1, 2, 3, 4), pay = c(10, 12, 13, 16, 19))
fit <- lm(pay ~ educ16, data = workers)
summary(fit)
confint(fit)
anova(fit)
R: what it prints
> # five made-up workers: years of education after 16 and hourly pay in pounds
> workers <- data.frame(educ16 = c(0, 1, 2, 3, 4), pay = c(10, 12, 13, 16, 19))
> fit <- lm(pay ~ educ16, data = workers)
> summary(fit)

Call:
lm(formula = pay ~ educ16, data = workers)

Residuals:
   1    2    3    4    5
 0.4  0.2 -1.0 -0.2  0.6

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept)   9.6000     0.5657  16.971 0.000446 ***
educ16        2.2000     0.2309   9.526 0.002453 **
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1

Residual standard error: 0.7303 on 3 degrees of freedom
Multiple R-squared:  0.968,	Adjusted R-squared:  0.9573
F-statistic: 90.75 on 1 and 3 DF,  p-value: 0.002453

> confint(fit)
               2.5 %    97.5 %
(Intercept) 7.799737 11.400263
educ16      1.465046  2.934954
> anova(fit)
Analysis of Variance Table

Response: pay
          Df Sum Sq Mean Sq F value   Pr(>F)
educ16     1   48.4  48.400   90.75 0.002453 **
Residuals  3    1.6   0.533
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1
Python: the code
import pandas as pd
import statsmodels.formula.api as smf

# five made-up workers: years of education after 16 and hourly pay in pounds
workers = pd.DataFrame({"educ16": [0, 1, 2, 3, 4], "pay": [10, 12, 13, 16, 19]})
fit = smf.ols("pay ~ educ16", data=workers).fit()
print(fit.summary())
Python: what it prints
                            OLS Regression Results
==============================================================================
Dep. Variable:                    pay   R-squared:                       0.968
Model:                            OLS   Adj. R-squared:                  0.957
Method:                 Least Squares   F-statistic:                     90.75
Date:                Thu, 08 Oct 2026   Prob (F-statistic):            0.00245
Time:                        14:49:33   Log-Likelihood:                -4.2461
No. Observations:                   5   AIC:                             12.49
Df Residuals:                       3   BIC:                             11.71
Df Model:                           1
Covariance Type:            nonrobust
==============================================================================
                 coef    std err          t      P>|t|      [0.025      0.975]
------------------------------------------------------------------------------
Intercept      9.6000      0.566     16.971      0.000       7.800      11.400
educ16         2.2000      0.231      9.526      0.002       1.465       2.935
==============================================================================
Omnibus:                          nan   Durbin-Watson:                   1.725
Prob(Omnibus):                    nan   Jarque-Bera (JB):                0.641
Skew:                          -0.795   Prob(JB):                        0.726
Kurtosis:                       2.262   Cond. No.                         4.74
==============================================================================

Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.
Stata prints them above the coefficient table as Model (48.4), Residual (1.6) and Total (50). R's anova(fit) lists 48.4 and 1.6 under Sum Sq, and the total is their sum. Python's statsmodels prints R-squared but not the sums of squares; they are stored as fit.ess, fit.ssr and fit.centered_tss, where ssr is the sum of squared residuals.
3. What does R-squared look like on real data?
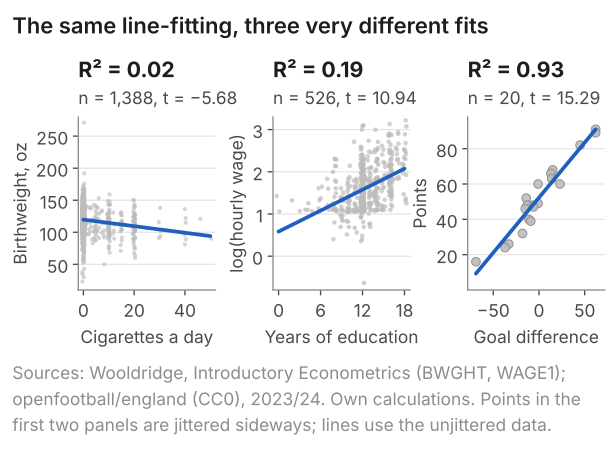
Figure 2 shows three real regressions, each fitted by the same method, with R-squared of 0.02, 0.19 and 0.93.
| Regression | n | R-squared |
|---|---|---|
| Birthweight on cigarettes a day in pregnancy | 1,388 | 0.023 |
| Log wage on years of education | 526 | 0.186 |
| Log wage on education, experience and tenure | 526 | 0.316 |
| Premier League points on goal difference, 2023/24 | 20 | 0.929 |
| Five workers: pay on education (made-up data) | 5 | 0.968 |
In the left-hand panel the line is almost lost in the cloud: cigarettes account for 2% of the variation in birthweight. In the right-hand panel the 20 clubs sit close to the line: goal difference accounts for 93% of the variation in points. In the middle panel education accounts for 19% of the variation in log wages, and adding experience and tenure raises that to 32%.
4. What is a good R-squared?
There is no threshold. Whether an R-squared is high or low depends on what is being explained, and whether it matters depends on what the regression is for.
A low R-squared does not mean the slope is wrong or unimportant. In the birthweight regression, on a sample of 1,388 births, R-squared is 0.023, yet the slope of -0.51 ounces per cigarette a day has a t-statistic of -5.68 and a 95% confidence interval of -0.69 to -0.34. The relationship is clearly there, and twenty cigarettes a day goes with about 10 ounces less. R-squared is low because most of the variation in birthweight comes from other sources. How precisely a slope is estimated is shown by its standard error, not by R-squared; the guide to regression output covers that. The three regressions on real data about individual people in the table above all have an R-squared below 0.35, because individual outcomes vary for many reasons that are not among the regressors (the explanatory variables).
A high R-squared does not mean the model is right or the relationship causal. In the Premier League regression R-squared is 0.93, but points and goal difference are two summaries of the same 38 matches. The close fit says that the two move together, not that one produces the other. The next section shows how different the data behind a single R-squared can be.
What R-squared is good for is a narrower question: for this dependent variable and this sample, how much of the variation do the regressors account for? That matters most when the purpose is prediction.
5. Four data sets with the same R-squared
Figure 3 shows four sets of 40 points, which we built so that the comparison is exact. In each one the least-squares line is y = 10 + 2x and R-squared is 0.50. (The idea of matching the regression output across very different data sets is due to Anscombe, who published four such sets in 1973; the four here are new.)
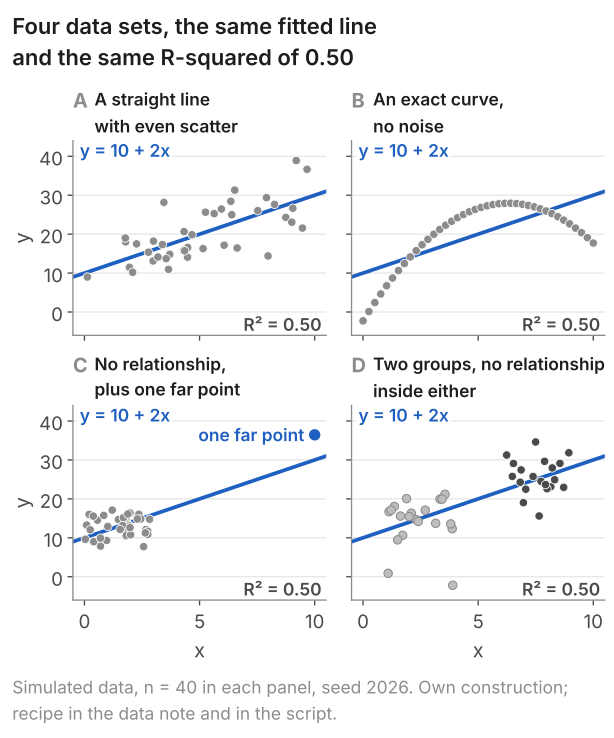
- A. A straight line with even scatter. The relationship is a straight line and the points are scattered evenly around it. Here the line and its R-squared are a fair summary.
- B. An exact curve, with no noise. Every point lies exactly on the curve y = -2.28 + 9.56x - 0.756x2. Knowing x tells us y perfectly, yet the straight line accounts for only half the variation, and it slopes up through data that fall after x = 6.3.
- C. No relationship, plus one far point. Among the 39 points on the left the slope is exactly zero and R-squared is exactly zero. The whole fit comes from the single point at x = 10. Remove it and nothing is left.
- D. Two groups. Inside each group the slope is zero. The line is produced by the gap between the groups, whose mean values of y are 14.2 and 25.8. It says the groups differ; it does not say that y rises with x within either of them.
The slope's row of the regression output is identical in all four: coefficient 2, standard error 0.324, t = 6.16. So is R-squared. Nothing in those numbers shows which of the four situations we are in. A plot does, which is the reason to look at the data before reading R-squared, or anything else in the table.
6. Why does R-squared never fall when you add a variable?
Suppose we add a regressor to a model. Least squares now chooses one more coefficient. One of its options is to set the new coefficient to zero and keep the others as they were, which would reproduce the old fit exactly. So the smallest sum of squared residuals it can reach is no larger than before. RSS cannot rise, TSS has not changed, and so R-squared = 1 - RSS/TSS cannot fall.
This is true whether or not the new variable has anything to do with y. To see it, we added columns of random numbers to the wage regression of log wage on education, experience and tenure, one column at a time.
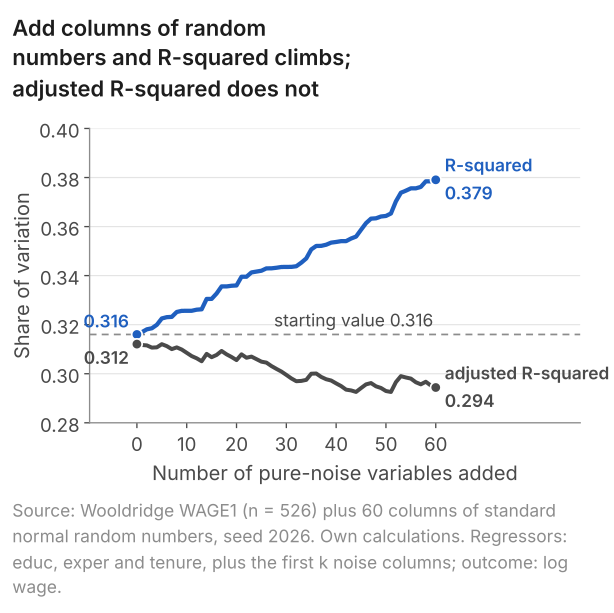
The random columns are unrelated to wages by construction. In this draw not one of the 60 has a statistically significant coefficient (by chance about three would be expected to). R-squared still rises with every column, from 0.316 to 0.379, because each column happens to line up slightly with the leftover variation in this particular sample, and that is enough to lower RSS. The consequence is that when one model contains all the regressors of another, the larger one always fits at least as well, so R-squared cannot tell us whether the extra variables belong. Adding a regressor can also change the other coefficients, not only R-squared; lesson 12 shows when and why.
7. What is the difference between R-squared and adjusted R-squared?
Adjusted R-squared corrects for this by dividing each sum of squares by its degrees of freedom: for RSS, the number of observations minus the number of coefficients estimated, and for TSS, the number of observations minus one. With \(n\) observations and \(k\) regressors (not counting the intercept):
$$ \begin{aligned} \bar R^2 &= 1 - \frac{\text{RSS}/(n-k-1)}{\text{TSS}/(n-1)} \\ &= 1 - (1 - R^2)\,\frac{n-1}{n-k-1} . \end{aligned} $$In words: take the unexplained share, 1 - R-squared, scale it up by (n - 1)/(n - k - 1), and subtract from 1.
For the wage regression, \(n = 526\), \(k = 3\) and R-squared is 0.3160:
$$ \begin{aligned} \bar R^2 &= 1 - (1 - 0.3160)\times\frac{525}{522} \\ &= 1 - 0.6840 \times 1.00575 = 0.3121 . \end{aligned} $$With three regressors and 526 observations the penalty is small. Add the 60 columns of random numbers and it is not: R-squared has risen to 0.379, while the adjusted figure, 1 - (1 - 0.379) × 525/462 = 0.294, is lower than where it started.
An extra regressor now has two effects. It lowers RSS, which raises adjusted R-squared, and it uses up a degree of freedom, which lowers it. Adjusted R-squared rises only when the first effect is the larger, which happens exactly when the new variable's t-statistic is above 1 in absolute value (the derivation is in the block below). A column of pure noise manages that some of the time: in Figure 4 the grey line rose at 18 of the 60 steps and fell at the other 42. So, unlike R-squared, adjusted R-squared can fall when a variable is added, and it can be negative for a regression that explains very little. Use it, rather than R-squared, to compare regressions that have the same dependent variable and different numbers of regressors. It is still a measure of fit and has the same limits as R-squared in every other respect.
Show why the cut-off is a t-statistic of 1
- The condition. Write \(d\) for the residual degrees of freedom after the variable is added, so there were \(d + 1\) before. TSS does not change, so adjusted R-squared rises when the residual sum of squares per degree of freedom falls: \(\text{RSS}_{\text{new}}/d < \text{RSS}_{\text{old}}/(d + 1)\).
- Rearrange. Multiplying out gives \((d + 1)\,\text{RSS}_{\text{new}} < d\,\text{RSS}_{\text{old}}\), that is, \(\text{RSS}_{\text{new}} < d\,(\text{RSS}_{\text{old}} - \text{RSS}_{\text{new}})\).
- Recognise the t-statistic. For one added variable, the square of its t-statistic is the fall in RSS divided by the new residual variance: \(t^2 = (\text{RSS}_{\text{old}} - \text{RSS}_{\text{new}})/(\text{RSS}_{\text{new}}/d)\). So the condition is \(t^2 > 1\).
8. Why is R-squared misleading with trending time series?
Economic time series such as prices and output move in one direction for years at a time. Two series that both wander in this way can move together over a sample even if they are unrelated, and a regression of one on the other then gives a high R-squared that means nothing.
A simulation shows how often this happens. A random walk is a series in which each value is the previous value plus a new random step, so it wanders with no tendency to return. Generate two random walks of 100 periods, each from its own independent random numbers, regress one on the other, and repeat 10,000 times. The average R-squared is 0.24. It is above 0.25 in 40% of the pairs and above 0.5 in 16%, and the usual t-test declares the slope significant at the 5% level in 77% of them, although no pair is related. For comparison, with two independent series of plain random numbers, which do not wander, the average R-squared is 0.01 and not one of the 10,000 pairs reaches 0.25.
This is the spurious regression problem, demonstrated by Granger and Newbold in 1974. With trending data a high R-squared is weak evidence of a relationship. The remedies, such as working with the changes in each series instead of the levels, belong to time-series econometrics: lesson 24 runs this experiment in levels and in changes at three sample sizes, and the time series notes set out the first definitions.
9. Common mistakes
- Treating a high R-squared as proof that the model is right. Panels B, C and D of Figure 3 all have the same R-squared as panel A.
- Treating a low R-squared as proof that the regression has failed. The birthweight slope is estimated precisely with an R-squared of 0.023.
- Trying to maximise R-squared. It rises with every added regressor, including columns of random numbers.
- Comparing R-squared across different dependent variables. Regressing the wage in dollars on education gives 0.165, and regressing the log wage gives 0.186. The two are shares of different totals (the variation in wages and the variation in log wages), so the comparison does not show which model fits better.
- Reading R-squared as the share of observations the line predicts correctly. It is a share of squared variation. With an R-squared of 0.93, none of the 20 clubs lies exactly on the line.
- Mixing up the letters. SSE is the explained sum of squares in some books and the error sum of squares in others. Write out which you mean.
10. Check your understanding
Five questions, marked on the page; every option has an explanation, including the wrong ones. (Without JavaScript the explanations are shown beneath each question.)
1. A regression has a total sum of squares of 80 and a residual sum of squares of 20. What is R-squared?
20/80 = 0.25 is the share of the variation left in the residuals. R-squared is the other part: 1 - 0.25.
20/60 compares the residual sum of squares with the explained one. R-squared compares the explained part with the total, 60/80.
Correct. R-squared = 1 - RSS/TSS = 1 - 20/80 = 0.75. Equivalently the explained sum of squares is 80 - 20 = 60, and 60/80 = 0.75.
2. You add a column of random numbers to a regression as an extra explanatory variable. What happens to R-squared?
Correct. The old fit is still available with a zero coefficient on the new column, so the smallest sum of squared residuals can only stay the same or fall. In the wage regression one column of random numbers moves R-squared from 0.3160 to 0.3170.
Least squares never has to use a variable that does not help: a zero coefficient leaves the fit unchanged. In the sample, a random column always picks up a little chance correlation, so the fit improves slightly.
It rises whenever the new coefficient is not exactly zero, which is almost always. Significance is a separate test; none of 60 random columns added to the wage regression was significant, and R-squared still rose from 0.316 to 0.379.
3. Adding one variable to a regression with 526 observations raises R-squared from 0.31601 to 0.31696, while adjusted R-squared falls from 0.31208 to 0.31172. What does the fall tell you?
It can, and in Figure 4 it did at 42 of the 60 steps. Adjusted R-squared divides each sum of squares by its degrees of freedom, so a small gain in fit can be outweighed by the degree of freedom the new variable uses.
Correct. Adjusted R-squared rises only if the new variable's t-statistic is above 1 in absolute value, which is roughly when it reduces the residual sum of squares by more than a pure-noise variable would be expected to.
Correlation among regressors does not by itself lower adjusted R-squared. What matters is how much the new variable reduces the residual sum of squares relative to the degree of freedom it costs.
4. Regressing log wage on education for 526 workers gives a slope of 0.083 (t = 10.9) and an R-squared of 0.19. A classmate says that with a fit this low the estimated slope cannot be trusted. Which reply is right?
How well the slope is estimated is measured by its standard error, not by R-squared. A t-statistic of 10.9 says the slope is estimated precisely.
Correct. R-squared says how much of the variation in pay education accounts for, and the answer is 19%, because experience, occupation, ability and luck matter too. The slope says how pay differs with education on average, and it is clearly not zero.
Adding variables raises R-squared whether or not they belong, so a high R-squared reached that way shows nothing. Whether the slope on education can be trusted depends on its standard error and on what is left in the error, not on the fit.
5. A computer generates two random walks of 100 periods, each built from its own independent random numbers. Regressing one on the other gives an R-squared of 0.60. What does the 0.60 show?
Correct. Each random walk drifts for long stretches, and two drifting series often move together over a sample by chance. In 10,000 simulated pairs like this one, R-squared was above 0.5 in 16% of them.
No mistake is needed. The steps are independent, but the levels of the two series are sums of steps, and sums wander. That is enough to produce a high R-squared quite often.
The series were built to be unrelated, so nothing causes anything here. R-squared measures how closely two columns of numbers line up in the sample, whatever the reason.
11. Questions people ask
There is no general threshold. It depends on what is being explained. In the real-data examples on this page it runs from 0.02, for birthweight on cigarettes with a precisely estimated slope, to 0.93, for league points on goal difference. A low value does not make a coefficient unreliable, and a high value does not make a model correct.
R-squared is the share of variation in the dependent variable that the regression accounts for, and it never falls when a regressor is added. Adjusted R-squared divides each sum of squares by its degrees of freedom, so it rises only if the new variable's t-statistic is above 1 in absolute value. Use it to compare models of different sizes.
TSS, the total sum of squares, is the sum of squared deviations of y from its mean. ESS, the explained sum of squares, is the same sum for the fitted values. RSS, the residual sum of squares, is the sum of squared residuals. In an OLS regression with an intercept, TSS = ESS + RSS, and R-squared is ESS/TSS.
Not in an OLS regression with an intercept, where it lies between 0 and 1. Computed as 1 - RSS/TSS, it can be negative for a regression without an intercept, or for a model assessed on data it was not fitted to, because the fit can then be worse than predicting the mean. Adjusted R-squared can also be negative.
12. Where next
- Lesson 10: residuals, fit and R-squared, which works through the decomposition on 20 real data points, with five more marked questions.
- How to read regression output, for the standard errors, t-statistics and intervals that sit beside R-squared in the table.
- What is OLS?, for the regression whose fit R-squared summarises.
- Diagnostic tests for the linear model and the Gauss-Markov theorem, for the questions R-squared does not answer.
- ARMA estimation and model selection, for AIC and BIC, which penalise extra parameters in time-series models.
Send me your regression: module, output and deadline
I tutor econometrics one-to-one, from a first regression through to endogeneity, panel data and time series. Bring the output you are stuck on and we will read it together in the free 30-minute consultation.
Book a free 30-minute consultation Econometrics tutor: how it works
Data and figures. Five-worker example: illustrative data. Birthweight and pay: Wooldridge, Introductory Econometrics: A Modern Approach, data sets BWGHT (1,388 births, 1988 National Health Interview Survey) and WAGE1 (526 workers, 1976), via the wooldridge Python package; results quoted, data not republished. Premier League: openfootball/england (CC0), 2023/24, with the deductions for Everton (8 points) and Nottingham Forest (4) applied. Figure 3 recipe. Random numbers from numpy's default_rng(2026). A: x uniform on 0 to 10, normal noise made exactly uncorrelated with x and scaled to give R-squared 0.50. B: 40 equally spaced x from 0 to 10 on a quadratic chosen so that the straight-line R-squared is 0.50. C: 39 points with x uniform on 0 to 3 and noise with exactly zero slope, plus one point at x = 10 placed to give R-squared 0.50. D: 20 points with x uniform on 1 to 4 and 20 with x uniform on 6 to 9, zero slope within each group, the second group shifted up to give R-squared 0.50. Each data set was then rescaled so that the fitted line is exactly 10 + 2x. Figure 4 and the random-walk simulation also use default_rng(2026): 60 columns of standard normal numbers for the wage regression; 10,000 pairs of 100-step random walks (cumulated standard normals) and 10,000 pairs of white noise. Scripts and full results are kept with the page's source files.