
1. What OLS is for, and what it does
Suppose we want to know how pay changes with education. We collect data on a sample of workers and plot pay against years of education. The points do not lie on a line. Two workers with the same education are paid differently, because pay also depends on experience, occupation, ability and luck. Still, the cloud of points leans upwards, and we would like to summarise that lean in one number: how much more, on average, a worker with one more year of education is paid.
A straight line through the cloud gives that number as its slope. The difficulty is that many different lines pass through a cloud of points, and two people drawing one by eye will not draw the same one. We need a rule that picks out a single line, so that anyone with the same data gets the same answer.
Ordinary least squares (OLS) is the standard rule for doing this. For any candidate line, measure how far each point lies above or below it. That vertical gap is what the line gets wrong for that observation. A good line leaves small gaps. OLS squares each gap, so that a miss above the line and a miss below it both count as positive, adds the squares up, and chooses the line for which the total is smallest. The gaps left by the chosen line are called its residuals. Intuitively, it is the line closest to the data, with closeness measured by the squared vertical gaps.
That is where the name comes from. Least squares: the line with the smallest sum of squared residuals. Ordinary: every observation counts equally in that sum. Weighted and generalised least squares, which come later in an econometrics course, let some observations count for more than others.
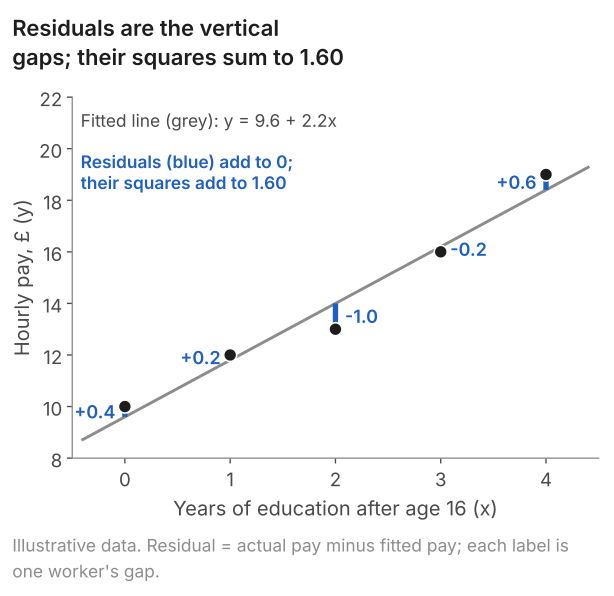
The true line, a trial line and the fitted line
To write the method down we need symbols for three different lines.
Notation and definition: three lines
The true line. We suppose that in the population the sample was drawn from, \(y\) and \(x\) are related by
$$ y_i = \beta_0 + \beta_1 x_i + u_i . $$Here \(\beta_0\) and \(\beta_1\) are the intercept and slope of the true regression line. They are fixed numbers, and we do not know them. The error \(u_i\) collects everything else that moves \(y_i\).
A trial line. Any intercept \(b_0\) and slope \(b_1\) give a candidate line \(b_0 + b_1 x\). For our sample of \(n\) pairs \((x_i, y_i)\), add up the squares of the vertical gaps it leaves:
$$ S(b_0, b_1) = \sum_{i=1}^{n}\bigl(y_i - b_0 - b_1 x_i\bigr)^2 . $$\(S\) is the objective function of the method: the quantity OLS makes as small as possible. It is a function of the two trial values, \(b_0\) and \(b_1\). The \(x_i\) and \(y_i\) are the numbers in our sample, and they stay fixed while \(b_0\) and \(b_1\) vary. Each pair of trial values gives a different line, a different set of gaps and a different value of \(S\). For the five workers in Figure 1, \(S(10, 2) = 2.00\), \(S(8, 3) = 8.00\) and \(S(9.6, 2.2) = 1.60\).
The fitted line. OLS solves the problem
$$ \min_{b_0,\,b_1}\; S(b_0, b_1) . $$The OLS estimates \(\hat\beta_0\) and \(\hat\beta_1\) (read "beta-hat") are the values of \(b_0\) and \(b_1\) at which \(S(b_0, b_1)\) is smallest. This is the definition of ordinary least squares. The fitted line is \(\hat y = \hat\beta_0 + \hat\beta_1 x\), and the gaps it leaves are the residuals.
Remarks. \(S\) is written with \(b_0\) and \(b_1\), and not with \(\beta_0\) and \(\beta_1\), because \(\beta_0\) and \(\beta_1\) are not ours to vary. Each is a single number, fixed by the population and unknown to us. We could not even work out \(S\) at those values: it would be the sum of the squared errors \(u_i\), and the errors are never observed. So the search is over trial values that we choose, and the hat marks where the search ends. \(\hat\beta_0\) and \(\hat\beta_1\) are computed from the sample. Another sample would give different ones, while \(\beta_0\) and \(\beta_1\) would be unchanged.
Nor is the fitted line the true line. Suppose the true line for these workers were \(10 + 2x\). Its \(S\) would be 2.00, more than the 1.60 of the fitted line. The fitted line is the one that suits this sample best, which is a different thing from being true.
Other books use other letters (\(a\) and \(b\), or \(\alpha\) and \(\beta\), for the intercept and slope). The difference is cosmetic: a symbol is only a label that shows which of the three lines is meant.
What "minimise" means: the data are fixed and the line varies
For the five workers in Figure 1 the data are the pairs (0, 10), (1, 12), (2, 13), (3, 16) and (4, 19). They do not change. What we are free to change is the line, and Figure 2 shows what happens to \(S\) as one of the two trial values, the slope, is varied.
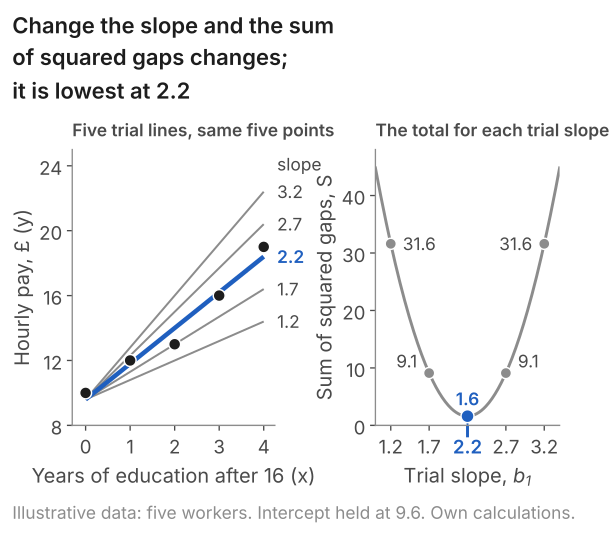
Hold the intercept at 9.6 and try five slopes. A slope of 1.2 gives a line that is too flat: it runs well below the later points, the gaps are large, and \(S = 31.6\). Steepen the line to 1.7 and \(S\) falls to 9.1. At 2.2 it is 1.6. Steepen it further and the line overshoots, so \(S\) rises again: 9.1 at a slope of 2.7 and 31.6 at 3.2. Plotted against the slope, with the intercept held at 9.6, \(S\) is a U-shaped curve with its bottom at 2.2. (The bottom is at the least-squares slope because 9.6 is the least-squares intercept. Hold the intercept at 8.6 instead and the bottom of the curve moves to a slope of 2.53. The two values have to be found together.)
The same happens if we hold the slope at 2.2 and move the intercept: \(S\) is 6.6 at an intercept of 8.6, 1.6 at 9.6, and 6.6 again at 10.6. With both parameters free, \(S\) is a bowl-shaped surface over all the pairs \((b_0, b_1)\), and OLS picks the pair at its lowest point: \(\hat\beta_0 = 9.6\) and \(\hat\beta_1 = 2.2\). This is what a minimisation problem does in general. The data are held fixed, the parameters are varied, and we look for the parameter values that bring the line closest to the data.
What is the OLS formula?
For a straight line we do not have to search. \(S\) is a smooth function of \(b_0\) and \(b_1\), so calculus finds the bottom of the bowl directly: differentiate \(S\) with respect to \(b_0\) and with respect to \(b_1\), set both derivatives to zero, and solve the two equations. With one explanatory variable the solution is
$$ \hat\beta_1 = \frac{\sum_{i=1}^{n}(x_i-\bar{x})(y_i-\bar{y})}{\sum_{i=1}^{n}(x_i-\bar{x})^2} $$ $$ \hat\beta_0 = \bar{y} - \hat\beta_1\bar{x} $$In words: slope = covariance of x and y divided by variance of x; intercept = mean of y minus slope times mean of x.
So the slope is a covariance scaled by a variance. If x and y move together the numerator is positive and the line slopes up; the denominator turns "how much they move together" into "how much y changes per unit of x". The intercept formula says that the fitted line passes through the point of means \((\bar x, \bar y)\). If covariance and variance are hazy, read lesson 3 of the course first.
Show the derivation, step by stepHide the derivation
You can use the two formulas without this. It is here for readers who want to see where they come from; it needs partial derivatives and the chain rule.
- The function to minimise. The data are fixed; the variables are \(b_0\) and \(b_1\). $$ S(b_0, b_1) = \sum_{i=1}^{n}(y_i - b_0 - b_1 x_i)^2 $$
- Differentiate with respect to the intercept. Each term is a square, so the chain rule gives twice the bracket times the derivative of the bracket, which is \(-1\). $$ \frac{\partial S}{\partial b_0} = -2\sum_{i=1}^{n}(y_i - b_0 - b_1 x_i) $$
- Differentiate with respect to the slope. The same, except that the derivative of the bracket is now \(-x_i\). $$ \frac{\partial S}{\partial b_1} = -2\sum_{i=1}^{n}x_i(y_i - b_0 - b_1 x_i) $$
- Set both to zero. At the bottom of the bowl the surface is flat in both directions. Call the values there \(\hat\beta_0\) and \(\hat\beta_1\), and write \(\hat u_i = y_i - \hat\beta_0 - \hat\beta_1 x_i\) for the residuals. The two conditions are $$ \sum_{i=1}^{n}\hat u_i = 0 \quad\text{and}\quad \sum_{i=1}^{n}x_i\hat u_i = 0 . $$ In words: the residuals add to zero, and they are uncorrelated with x in the sample. These are the first-order conditions, also called the normal equations.
- Solve the first condition for the intercept. Written out, it is \(\sum y_i - n\hat\beta_0 - \hat\beta_1\sum x_i = 0\). Divide by \(n\): $$ \hat\beta_0 = \bar y - \hat\beta_1 \bar x . $$
- Substitute into the second condition. Replacing \(\hat\beta_0\) turns the residual into \((y_i - \bar y) - \hat\beta_1(x_i - \bar x)\), so $$ \begin{aligned} & \sum_{i=1}^{n}x_i(y_i - \bar y) \\ & \quad = \hat\beta_1\sum_{i=1}^{n}x_i(x_i - \bar x) . \end{aligned} $$
- Tidy the two sums. Deviations from a mean add to zero, so \(\sum \bar x(y_i - \bar y) = 0\) and \(\sum \bar x(x_i - \bar x) = 0\). Subtracting these from the two sides changes nothing and gives $$ \hat\beta_1 = \frac{\sum_{i=1}^{n}(x_i-\bar{x})(y_i-\bar{y})}{\sum_{i=1}^{n}(x_i-\bar{x})^2} . $$
- Check that it is a minimum. \(S\) is a sum of squares: it is never negative, and it grows without limit as the line moves away from the points, so the one flat point is the lowest point. This needs the denominator \(\sum(x_i - \bar x)^2\) to be positive, that is, the \(x\)'s must not all be equal.
- Check with the five workers. At \(b_0 = 9.6\), \(b_1 = 2.2\) the residuals are 0.4, 0.2, -1.0, -0.2, 0.6. They add to zero, and so do the products with x: 0(0.4) + 1(0.2) + 2(-1.0) + 3(-0.2) + 4(0.6) = 0. Both conditions hold.
With several explanatory variables the same steps give \(\hat{\boldsymbol\beta}=(\mathbf X'\mathbf X)^{-1}\mathbf X'\mathbf y\); the OLS matrix form and derivation page has the working.
What students say
“Nicky is an excellent econometrics tutor. He explains complex concepts clearly and makes them much easier to understand.”
“I was completely lost in my economics class, and then I started working Nicky and he totally saved me. He was excellent at explaining the material and extremely accommodating to meet with me many times despite us being in different time zones! Highly recommend working with Nicky!”
“Nicky is a very good and thorough teacher. He has excellent knowledge of econometrics and takes the time to work through your questions. Highly recommended!”
“Really great tutor! Encouraging, knowledgeable, friendly”
“Very good lesson, Nicky is very helpful.”
“Very helpful and clear.”
“I gather it was very useful, thank you!”
“Fantastic!”
2. What is the difference between OLS and linear regression?
In everyday use the two terms are interchangeable. "Run a linear regression" and "estimate it by OLS" are used to mean the same thing, and lm in R and regress in Stata use OLS by default. Strictly, though, they name two different things, and a good deal of econometrics depends on keeping them apart.
The linear regression model is an assumption about the population. It says that the true relationship between y and x is a straight line plus an error, \(y = \beta_0 + \beta_1 x + u\). This is a statement about how the data were generated. It may be true, roughly true or false, and nothing we compute can make it true.
OLS is an estimator: a rule applied to a sample. It takes the data and returns the intercept and slope that minimise the sum of squared residuals. We can apply it to any set of pairs \((x_i, y_i)\) in which the x values are not all the same, whatever produced them, and it always returns a straight line. (The rule is the estimator; the numbers it gives for one sample are the estimates.)
What the OLS line tells us therefore depends on the true model, not on the method. If the population relationship is a straight line, and the other conditions in section 8 hold, the OLS line estimates it: \(\hat\beta_1\) is centred on \(\beta_1\) across samples, and the more data we have, the closer to \(\beta_1\) it tends to be (the law of large numbers). If the true relationship is not a straight line, OLS still returns a line, but the fitted line cannot then be the true relationship. What it estimates is the best straight-line approximation to it: the line that makes the average squared vertical gap to the true relationship, over the whole population, as small as possible. Figure 3 shows both cases, using data we simulated so that the true relationship is known.
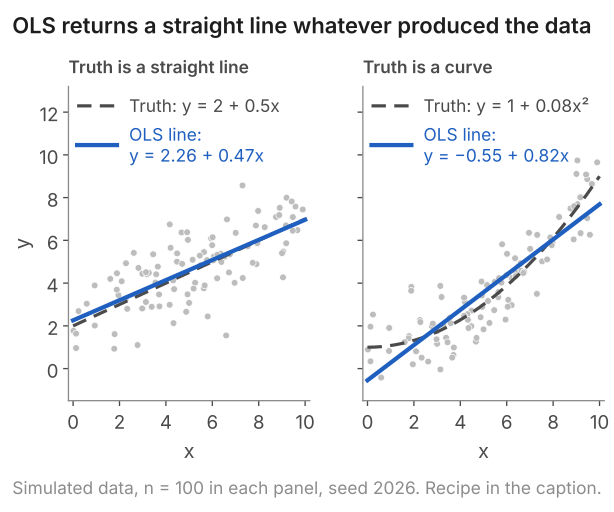
On the left the truth is \(y = 2 + 0.5x\), and OLS on 100 points gives 2.26 + 0.47x. The fitted line is almost on top of the true one, and the small gap is sampling error: a different 100 points would give a slightly different line, and such lines scatter around the true one.
On the right the truth is the curve \(y = 1 + 0.08x^2\). OLS returns -0.545 + 0.823x (rounded to -0.55 + 0.82x in the figure). That line predicts too little at both ends (by 1.5 at x = 0 and by 1.3 at x = 10) and too much in the middle (by 0.6 at x = 5). More data would not cure this. With a very large sample the fitted line would settle down, but to the best straight-line approximation, -0.33 + 0.8x, not to the curve. The remedy is to change the model, not the estimator: regress y on \(x^2\) by OLS, and the same 100 points give \(1.02 + 0.081x^2\), close to the true curve.
So a key assumption, if OLS is to uncover the underlying relationship, is that the relationship is linear in the sense of section 8: a straight line in x, or in some transformation of x such as its square or its logarithm. That is an assumption about the true model. It is separate from the decision to use OLS, and a plot of the data is the first check on it.
| The linear regression model | The OLS estimator | |
|---|---|---|
| What it is | An assumption about the population: \(y = \beta_0 + \beta_1 x + u\) | A rule applied to a sample: minimise the sum of squared residuals |
| What it contains | Fixed, unknown \(\beta_0\) and \(\beta_1\), and an error \(u\) we never observe | Computed \(\hat\beta_0\) and \(\hat\beta_1\), and residuals we can list |
| Can it be wrong? | Yes. The true relationship may be curved, or the error may move with x | No, in the sense that it always returns the least-squares line for the data it is given |
| How they connect | Says what \(\hat\beta_1\) is an estimate of | Whether it is unbiased and how precise it is depend on the true model |
The model and the method can also be combined in other ways. The same linear model can be estimated by other methods, such as least absolute deviations (which minimises absolute instead of squared residuals; section 6) or instrumental variables, and OLS can be applied to models that are not straight lines in x, as the regression on \(x^2\) above shows.
3. How to calculate OLS by hand: the five-worker example
Five workers. \(x\) is years of education after age 16 and \(y\) is hourly pay in pounds. The data are made up to keep the arithmetic short; the method is the one R, Stata and Python apply to samples of any size.
| Worker | x (years) | y (pounds) |
|---|---|---|
| Ana | 0 | 10 |
| Ben | 1 | 12 |
| Cara | 2 | 13 |
| Dev | 3 | 16 |
| Eli | 4 | 19 |
- Means. \(\bar x = 10/5 = 2\) and \(\bar y = 70/5 = 14\).
- Deviations from the means and their products. Subtract 2 from each x and 14 from each y, multiply the pairs (the product column), and square the x deviations.
The two deviation columns add to zero, which confirms the means are right.
Worker x y x - 2 y - 14 product (x - 2)2 Ana 0 10 -2 -4 8 4 Ben 1 12 -1 -2 2 1 Cara 2 13 0 -1 0 0 Dev 3 16 1 2 2 1 Eli 4 19 2 5 10 4 Sum 10 70 0 0 22 10 - Slope. \(\hat\beta_1 = 22/10 = 2.2\) pounds an hour per year of education.
- Intercept. \(\hat\beta_0 = 14 - 2.2 \times 2 = 9.6\) pounds an hour.
- Fitted values, residuals and the sum of squares. Put each x into \(\hat y = 9.6 + 2.2x\) and subtract the result from the actual y.
Worker y Fitted Residual Residual2 Ana 10 9.6 0.4 0.16 Ben 12 11.8 0.2 0.04 Cara 13 14.0 -1.0 1.00 Dev 16 16.2 -0.2 0.04 Eli 19 18.4 0.6 0.36 Sum 70 70.0 0.0 1.60
Checks (1) and (3) are the two first-order conditions from the derivation in section 1. They mean that OLS splits each \(y_i\) into a straight-line function of \(x_i\) and a leftover that is uncorrelated with \(x_i\) in the sample. This happens with any data, because the fitting forces it. Whether the true error is uncorrelated with x is a separate question about the model, which section 8 takes up. The leftover is the residual, which we can compute. The error \(u_i\) is the gap from the true line, which we never see.
4. What do the slope and the intercept mean?
The slope has units: y-units per x-unit. In the example, each extra year of education after 16 is associated with £2.20 more an hour, on average, across these five workers. "On average" because the line describes the typical worker at each x, not any one of them: Cara is paid £1.00 less than her fitted value. "Associated with" because nothing in the fitting rules out that something else, left in the error, moves with education. The standard argument is that more able people may earn more and may also stay in education longer, and if so part of the 2.2 is ability, not schooling. The correlation and causation page goes further; section 8 shows the same mechanism at work with variables that are in the data.
The intercept is the predicted y when x is zero. Whether that means anything depends on whether x = 0 is a real case in the data.
An intercept that means something
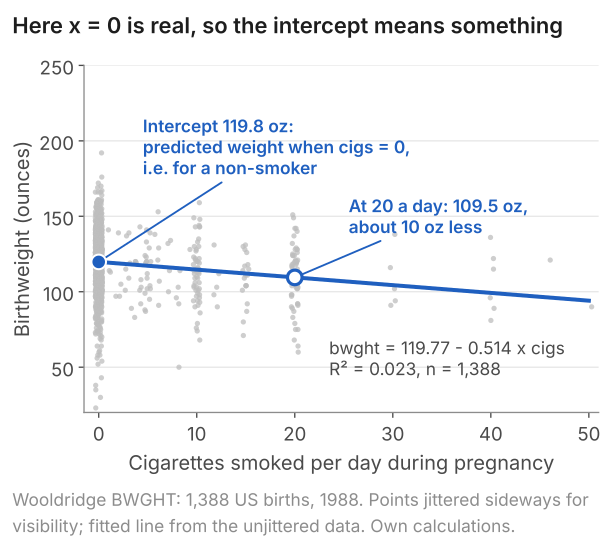
Regress birthweight on the number of cigarettes a mother smoked a day during pregnancy, using 1,388 US births recorded in the 1988 National Health Interview Survey (Wooldridge's BWGHT data).
Stata: the code
* once: ssc install bcuse
bcuse bwght, clear
regress bwght cigs
Stata: what it prints
. regress bwght cigs

      Source |       SS           df       MS      Number of obs   =     1,388
-------------+----------------------------------   F(1, 1386)      =     32.24
       Model |  13060.4194         1  13060.4194   Prob > F        =    0.0000
    Residual |    561551.3     1,386  405.159668   R-squared       =    0.0227
-------------+----------------------------------   Adj R-squared   =    0.0220
       Total |   574611.72     1,387  414.283864   Root MSE        =    20.129

------------------------------------------------------------------------------
       bwght | Coefficient  Std. err.      t    P>|t|     [95% conf. interval]
-------------+----------------------------------------------------------------
        cigs |  -.5137721   .0904909    -5.68   0.000    -.6912861   -.3362581
       _cons |   119.7719   .5723407   209.27   0.000     118.6492    120.8946
------------------------------------------------------------------------------
R: the code
library(wooldridge)
data("bwght")
fit <- lm(bwght ~ cigs, data = bwght)
summary(fit)
confint(fit)
R: what it prints
> library(wooldridge)
> data("bwght")
> fit <- lm(bwght ~ cigs, data = bwght)
> summary(fit)

Call:
lm(formula = bwght ~ cigs, data = bwght)

Residuals:
    Min      1Q  Median      3Q     Max
-96.772 -11.772   0.297  13.228 151.228

Coefficients:
             Estimate Std. Error t value Pr(>|t|)
(Intercept) 119.77190    0.57234 209.267  < 2e-16 ***
cigs         -0.51377    0.09049  -5.678 1.66e-08 ***
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1

Residual standard error: 20.13 on 1386 degrees of freedom
Multiple R-squared:  0.02273,	Adjusted R-squared:  0.02202
F-statistic: 32.24 on 1 and 1386 DF,  p-value: 1.662e-08

> confint(fit)
                  2.5 %      97.5 %
(Intercept) 118.6491529 120.8946479
cigs         -0.6912861  -0.3362581
Python: the code
import wooldridge
import statsmodels.formula.api as smf

bwght = wooldridge.data("bwght")
fit = smf.ols("bwght ~ cigs", data=bwght).fit()
print(fit.summary())
Python: what it prints
                            OLS Regression Results
==============================================================================
Dep. Variable:                  bwght   R-squared:                       0.023
Model:                            OLS   Adj. R-squared:                  0.022
Method:                 Least Squares   F-statistic:                     32.24
Date:                Thu, 08 Oct 2026   Prob (F-statistic):           1.66e-08
Time:                        14:49:36   Log-Likelihood:                -6135.5
No. Observations:                1388   AIC:                         1.227e+04
Df Residuals:                    1386   BIC:                         1.229e+04
Df Model:                           1
Covariance Type:            nonrobust
==============================================================================
                 coef    std err          t      P>|t|      [0.025      0.975]
------------------------------------------------------------------------------
Intercept    119.7719      0.572    209.267      0.000     118.649     120.895
cigs          -0.5138      0.090     -5.678      0.000      -0.691      -0.336
==============================================================================
Omnibus:                      118.187   Durbin-Watson:                   1.924
Prob(Omnibus):                  0.000   Jarque-Bera (JB):              635.742
Skew:                          -0.156   Prob(JB):                    8.92e-139
Kurtosis:                       6.301   Cond. No.                         6.72
==============================================================================

Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.
Here 85% of the mothers smoked nothing, so x = 0 is the commonest case in the data and the intercept is a prediction about real people: 119.8 ounces, about 3.4 kilograms. We can check it against the raw averages. Babies of non-smokers in the sample weigh 120.1 oz on average, babies of smokers 111.1 oz. Each cigarette a day goes with about half an ounce less, so twenty a day goes with about 10 ounces (290 grams) less.
An intercept that does not
Regress hourly pay in dollars on years of education for 526 US workers in 1976 (Wooldridge's WAGE1 data) and we get wage = -0.90 + 0.541 × educ. Read literally, the intercept says a worker with no schooling earns minus 90 cents an hour. The two people in the sample with zero years of education actually earned $4.17 and $2.89. The arithmetic is right; the reading is wrong. Of the 526 workers, 508 have between 8 and 18 years of education, so the line is fitted to that range and then extended far outside it. Pay also rises faster with each extra year at higher levels of education, so a straight line extended back to zero undershoots. This is the situation in the right-hand panel of Figure 3: a straight line fitted to a relationship that curves. (This curvature is one reason for using the log of pay as the dependent variable, as section 7 does.)
If x = 0 is impossible or far outside the data, subtract the mean from x before running the regression. The slope is unchanged and the intercept becomes the predicted y for an average observation. When x has a natural zero, the intercept can be the number we want: in the Premier League example below, average goal difference is zero by construction, so the intercept is exactly the average points total.
5. What the software prints, and what the extra columns mean
Give the five pairs to Stata, R or Python (the commands are under the table). The first column of the results repeats the two numbers we found by hand and interpreted in section 4. The remaining columns answer a question we have not yet asked: we have one sample of five workers, so how far might these estimates be from the true \(\beta_0\) and \(\beta_1\)?
| Term | Coefficient | Std. error | t | 95% interval |
|---|---|---|---|---|
| Intercept | 9.600 | 0.566 | 16.97 | 7.80 to 11.40 |
| educ16 (x, years after 16) | 2.200 | 0.231 | 9.53 | 1.47 to 2.93 |
n = 5, R-squared = 0.968, residual standard error = 0.730 pounds.
Stata: the code
clear
input educ16 pay
0 10
1 12
2 13
3 16
4 19
end
regress pay educ16
Stata: what it prints
. regress pay educ16

      Source |       SS           df       MS      Number of obs   =         5
-------------+----------------------------------   F(1, 3)         =     90.75
       Model |        48.4         1        48.4   Prob > F        =    0.0025
    Residual |         1.6         3  .533333333   R-squared       =    0.9680
-------------+----------------------------------   Adj R-squared   =    0.9573
       Total |          50         4        12.5   Root MSE        =     .7303

------------------------------------------------------------------------------
         pay | Coefficient  Std. err.      t    P>|t|     [95% conf. interval]
-------------+----------------------------------------------------------------
      educ16 |        2.2   .2309401     9.53   0.002     1.465046    2.934954
       _cons |        9.6   .5656854    16.97   0.000     7.799737    11.40026
------------------------------------------------------------------------------
R: the code
# five made-up workers: years of education after 16 and hourly pay in pounds
workers <- data.frame(educ16 = c(0, 1, 2, 3, 4), pay = c(10, 12, 13, 16, 19))
fit <- lm(pay ~ educ16, data = workers)
summary(fit)
confint(fit)
anova(fit)
R: what it prints
> # five made-up workers: years of education after 16 and hourly pay in pounds
> workers <- data.frame(educ16 = c(0, 1, 2, 3, 4), pay = c(10, 12, 13, 16, 19))
> fit <- lm(pay ~ educ16, data = workers)
> summary(fit)

Call:
lm(formula = pay ~ educ16, data = workers)

Residuals:
   1    2    3    4    5
 0.4  0.2 -1.0 -0.2  0.6

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept)   9.6000     0.5657  16.971 0.000446 ***
educ16        2.2000     0.2309   9.526 0.002453 **
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1

Residual standard error: 0.7303 on 3 degrees of freedom
Multiple R-squared:  0.968,	Adjusted R-squared:  0.9573
F-statistic: 90.75 on 1 and 3 DF,  p-value: 0.002453

> confint(fit)
               2.5 %    97.5 %
(Intercept) 7.799737 11.400263
educ16      1.465046  2.934954
> anova(fit)
Analysis of Variance Table

Response: pay
          Df Sum Sq Mean Sq F value   Pr(>F)
educ16     1   48.4  48.400   90.75 0.002453 **
Residuals  3    1.6   0.533
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1
Python: the code
import pandas as pd
import statsmodels.formula.api as smf

# five made-up workers: years of education after 16 and hourly pay in pounds
workers = pd.DataFrame({"educ16": [0, 1, 2, 3, 4], "pay": [10, 12, 13, 16, 19]})
fit = smf.ols("pay ~ educ16", data=workers).fit()
print(fit.summary())
Python: what it prints
                            OLS Regression Results
==============================================================================
Dep. Variable:                    pay   R-squared:                       0.968
Model:                            OLS   Adj. R-squared:                  0.957
Method:                 Least Squares   F-statistic:                     90.75
Date:                Thu, 08 Oct 2026   Prob (F-statistic):            0.00245
Time:                        14:49:33   Log-Likelihood:                -4.2461
No. Observations:                   5   AIC:                             12.49
Df Residuals:                       3   BIC:                             11.71
Df Model:                           1
Covariance Type:            nonrobust
==============================================================================
                 coef    std err          t      P>|t|      [0.025      0.975]
------------------------------------------------------------------------------
Intercept      9.6000      0.566     16.971      0.000       7.800      11.400
educ16         2.2000      0.231      9.526      0.002       1.465       2.935
==============================================================================
Omnibus:                          nan   Durbin-Watson:                   1.725
Prob(Omnibus):                    nan   Jarque-Bera (JB):                0.641
Skew:                          -0.795   Prob(JB):                        0.726
Kurtosis:                       2.262   Cond. No.                         4.74
==============================================================================

Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.
Take the slope's row, column by column.
- Coefficient. The estimate \(\hat\beta_1 = 2.2\): pay is £2.20 an hour higher per extra year of education, on average, in this sample.
- Standard error. Five different workers would have given a different slope. The standard error, 0.231, estimates the standard deviation of the slope across repeated samples: the square root of the average squared distance between one sample's slope and the population slope \(\beta_1\), on which the slopes are centred when nothing in the error moves with x (assumption 3 in section 8). Under random sampling, and if the errors have the same variance at every x, the variance of the slope is the error variance divided by the sum of squared x deviations, 10 here. We estimate the error standard deviation from the residuals, \(\sqrt{1.60/3} = 0.730\) pounds (the residual standard error; it divides by 3 because two numbers were estimated from five points), and the square root of the ratio, \(0.730/\sqrt{10} = 0.231\) (0.2309 before rounding), is in the units of the slope, pounds an hour per year. Lesson 11 builds it step by step.
- t. The coefficient divided by its standard error, 2.2/0.2309 = 9.53. The estimate is more than nine standard errors away from zero, which would be very unlikely if the true slope were zero.
- 95% interval. The coefficient plus and minus a multiple of the standard error: 2.2 ± 3.182 × 0.2309, which is 1.47 to 2.93. It is the range of true slopes compatible with the data. The multiple is 3.182 here, not the 1.96 used in large samples, because five observations leave only three degrees of freedom (five observations minus the two numbers estimated). Confidence intervals and t-tests explains where the multiple comes from and what "95%" does and does not mean.
Below the table, R-squared says that the line accounts for 96.8% of the variation in pay: 1 minus 1.60/50, where 50 is the sum of the squared distances of the five pays from their mean. The interval is wide, 1.47 to 2.93, even though the fit is tight: five observations cannot pin a slope down closely. (The multiple 3.182 is exact only if the errors are normally distributed, which five made-up points cannot tell us; the example shows the mechanics.)
The columns read the same way on real data. In the birthweight regression of Figure 4 the slope is -0.514 with a standard error of 0.090, so t = -5.7 and the 95% interval runs from -0.69 to -0.34: the true slope is clearly not zero. Yet R-squared is 0.023, so cigarettes account for only 2% of the variation in birthweight. Precision and fit are different things. With 1,388 births a small average difference can be measured precisely, even though most of the variation in birthweight has other causes.
The guide to reading regression output takes each column in turn on a real regression with 526 workers, and the R-squared page says what 0.968 does and does not mean.
6. Why do we square the residuals?
Section 1 took the squaring for granted. There are two questions in it. Why transform the residuals at all before adding them up? And why square them, when taking absolute values would also remove the signs? Three lines through the same five points help with both.
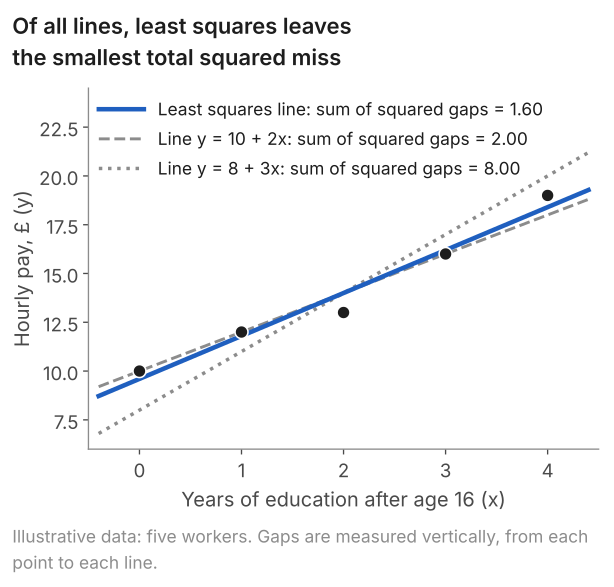
| Line | Gaps (pounds) | Sum of squared gaps |
|---|---|---|
| 9.6 + 2.2x (least squares) | 0.4, 0.2, -1.0, -0.2, 0.6 | 1.60 |
| 10 + 2x | 0, 0, -1, 0, 1 | 2.00 |
| 8 + 3x | 2, 1, -1, -1, -1 | 8.00 |
First, why not add the residuals as they are? Because positive and negative residuals cancel. The fitted line's residuals, +0.4, +0.2, -1.0, -0.2 and +0.6, add to exactly zero, and so do the gaps left by many worse lines (any line through the point of means leaves gaps that sum to zero). A total of zero cannot tell a good line from a bad one. Squaring removes the signs, so every miss adds to the total. Taking absolute values would remove the signs too. There are two reasons for preferring squares, and a third property of squares that can be a cost.
- Squares give a formula. The sum of squares is a smooth bowl when plotted against the intercept and slope (Figure 2 is a slice through it), so calculus finds the bottom and gives the formulas in section 1. The sum of absolute values is a surface with creases in it: there is no formula, the minimum has to be found by numerical search, and sometimes several lines tie for first place.
- Fitting a constant gives the mean. Suppose we summarise the five pays (10, 12, 13, 16, 19) by one number instead of a line. The sum of squared deviations is 55 about 13, 50 about 14 and 55 about 15: it is smallest at the mean, 14. The sum of absolute deviations is smallest at the median, 13 (a total of 13, against 14 about the mean). So least squares is the regression counterpart of the mean, and least absolute deviations is the counterpart of the median.
- Squares weight large misses heavily. A residual of 4 adds 16 to the total, as much as sixteen residuals of 1. That is useful when a large miss is real information and harmful when it is a data-entry error, as the click-to-open example below shows.
What one outlier does
Show what one mistyped point does to the lineHide the outlier example
Suppose Eli's pay is typed as 29 instead of 19.
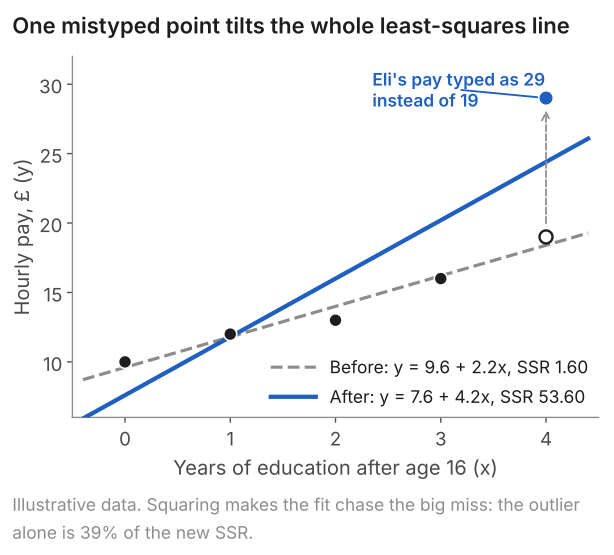
The slope nearly doubles, from 2.2 to 4.2. Eli's point now accounts for 39% of the sum of squares (4.62 = 21.2 of 53.6), and because he sits at the end of the x range the line can swing towards him cheaply. Had Cara's pay been mistyped instead, the intercept would move and the slope would stay at 2.2, because Cara sits at the mean of x. The absolute-value line stays at 10 + 2x, since it counts the size of a miss, not its square. This is one reason to plot the data before reading a slope.
7. Two real examples: football points and pay
Both are one-variable OLS regressions on data you can download and check; the code is under each figure. Look at what the line captures and at what it leaves in the residuals.
Premier League 2023/24: points against goal difference
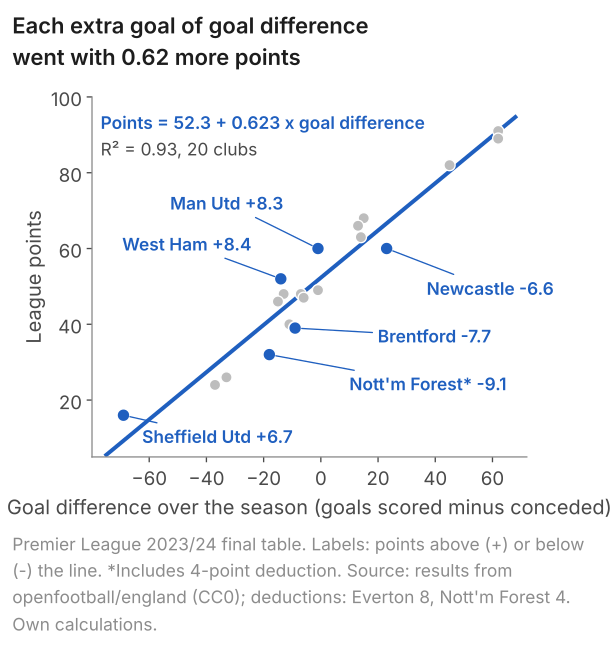
Read the slope as "about 0.62 points per goal of goal difference". The intercept, 52.3, is the average points total, because average goal difference across the 20 clubs is exactly zero (every goal scored is a goal conceded by someone) and the line passes through the point of means. Goal difference alone accounts for 93% of the variation in points, and a typical club finishes within about 6 points of the line. The residuals are the interesting part: West Ham finished 8 points above what their goal difference implied, Newcastle 7 below. Luck in close games, or a side that eased off with a lead, could each open a gap like that; the regression cannot say which. Nor is this causal: points and goal difference come out of the same 38 matches. Pool five seasons (100 club-seasons) and the line barely moves: 52.56 + 0.6036x, R-squared 0.925.
Stata: the code
import delimited "premier-league-2023-24.csv", clear
regress points gd
Stata: what it prints
. regress points gd

      Source |       SS           df       MS      Number of obs   =        20
-------------+----------------------------------   F(1, 18)        =    233.77
       Model |  7483.95222         1  7483.95222   Prob > F        =    0.0000
    Residual |  576.247782        18  32.0137657   R-squared       =    0.9285
-------------+----------------------------------   Adj R-squared   =    0.9245
       Total |      8060.2        19  424.221053   Root MSE        =    5.6581

------------------------------------------------------------------------------
      points | Coefficient  Std. err.      t    P>|t|     [95% conf. interval]
-------------+----------------------------------------------------------------
          gd |   .6234549   .0407763    15.29   0.000      .537787    .7091227
       _cons |       52.3   1.265183    41.34   0.000     49.64195    54.95805
------------------------------------------------------------------------------
R: the code
# Premier League 2023/24 final table: points (after deductions) and goal difference
pl <- read.csv("premier-league-2023-24.csv")
fit <- lm(points ~ gd, data = pl)
summary(fit)
confint(fit)
R: what it prints
> # Premier League 2023/24 final table: points (after deductions) and goal difference
> pl <- read.csv("premier-league-2023-24.csv")
> fit <- lm(points ~ gd, data = pl)
> summary(fit)

Call:
lm(formula = points ~ gd, data = pl)

Residuals:
   Min     1Q Median     3Q    Max
-9.078 -5.285  0.055  4.253  8.428

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept) 52.30000    1.26518   41.34  < 2e-16 ***
gd           0.62345    0.04078   15.29 9.36e-12 ***
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1

Residual standard error: 5.658 on 18 degrees of freedom
Multiple R-squared:  0.9285,	Adjusted R-squared:  0.9245
F-statistic: 233.8 on 1 and 18 DF,  p-value: 9.356e-12

> confint(fit)
                2.5 %     97.5 %
(Intercept) 49.641949 54.9580511
gd           0.537787  0.7091227
Python: the code
import pandas as pd
import statsmodels.formula.api as smf

# Premier League 2023/24 final table: points (after deductions) and goal difference
pl = pd.read_csv("premier-league-2023-24.csv")
fit = smf.ols("points ~ gd", data=pl).fit()
print(fit.summary())
Python: what it prints
                            OLS Regression Results
==============================================================================
Dep. Variable:                 points   R-squared:                       0.929
Model:                            OLS   Adj. R-squared:                  0.925
Method:                 Least Squares   F-statistic:                     233.8
Date:                Thu, 08 Oct 2026   Prob (F-statistic):           9.36e-12
Time:                        14:49:35   Log-Likelihood:                -61.987
No. Observations:                  20   AIC:                             128.0
Df Residuals:                      18   BIC:                             130.0
Df Model:                           1
Covariance Type:            nonrobust
==============================================================================
                 coef    std err          t      P>|t|      [0.025      0.975]
------------------------------------------------------------------------------
Intercept     52.3000      1.265     41.338      0.000      49.642      54.958
gd             0.6235      0.041     15.290      0.000       0.538       0.709
==============================================================================
Omnibus:                        2.895   Durbin-Watson:                   1.352
Prob(Omnibus):                  0.235   Jarque-Bera (JB):                1.209
Skew:                          -0.004   Prob(JB):                        0.546
Kurtosis:                       1.795   Cond. No.                         31.0
==============================================================================

Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.
The code reads premier-league-2023-24.csv (20 rows: club, points, gd). Save it in your working folder first.
Pay and schooling: 526 US workers
Show the second exampleHide the second example
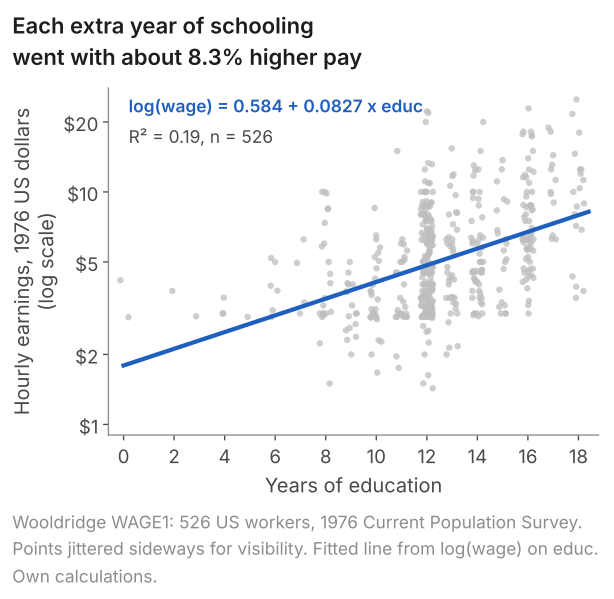
The cloud of points is wide. A slope of 0.0827 in a log-wage regression reads as "about 8.3% more pay per year of schooling": 100 times the coefficient. The exact figure is 8.6%: a difference of 0.0827 in log pay multiplies pay by \(e^{0.0827} = 1.086\). For a small number \(b\), \(e^{b}\) is close to \(1 + b\), so the percentage difference is close to \(100b\); the two readings drift apart as the slope grows. The logs and elasticities page has the details. Education accounts for 19% of the variation in log wages. The other 81% is in the residuals: experience, occupation, and ability, which is not in the data at all. Section 8 returns to ability.
Stata: the code
* once: ssc install bcuse
bcuse wage1, clear
regress lwage educ
Stata: what it prints
. regress lwage educ

      Source |       SS           df       MS      Number of obs   =       526
-------------+----------------------------------   F(1, 524)       =    119.58
       Model |  27.5606288         1  27.5606288   Prob > F        =    0.0000
    Residual |  120.769123       524  .230475425   R-squared       =    0.1858
-------------+----------------------------------   Adj R-squared   =    0.1843
       Total |  148.329751       525   .28253286   Root MSE        =    .48008

------------------------------------------------------------------------------
       lwage | Coefficient  Std. err.      t    P>|t|     [95% conf. interval]
-------------+----------------------------------------------------------------
        educ |   .0827444   .0075667    10.94   0.000     .0678796    .0976091
       _cons |   .5837727   .0973358     6.00   0.000     .3925563    .7749891
------------------------------------------------------------------------------
R: the code
library(wooldridge)
data("wage1")
fit <- lm(lwage ~ educ, data = wage1)
summary(fit)
confint(fit)
R: what it prints
> library(wooldridge)
> data("wage1")
> fit <- lm(lwage ~ educ, data = wage1)
> summary(fit)

Call:
lm(formula = lwage ~ educ, data = wage1)

Residuals:
     Min       1Q   Median       3Q      Max
-2.21158 -0.36393 -0.07263  0.29712  1.52339

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept) 0.583773   0.097336   5.998 3.74e-09 ***
educ        0.082744   0.007567  10.935  < 2e-16 ***
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1

Residual standard error: 0.4801 on 524 degrees of freedom
Multiple R-squared:  0.1858,	Adjusted R-squared:  0.1843
F-statistic: 119.6 on 1 and 524 DF,  p-value: < 2.2e-16

> confint(fit)
                 2.5 %     97.5 %
(Intercept) 0.39255627 0.77498906
educ        0.06787958 0.09760915
Python: the code
import wooldridge
import statsmodels.formula.api as smf

wage1 = wooldridge.data("wage1")
fit = smf.ols("lwage ~ educ", data=wage1).fit()
print(fit.summary())
Python: what it prints
                            OLS Regression Results
==============================================================================
Dep. Variable:                  lwage   R-squared:                       0.186
Model:                            OLS   Adj. R-squared:                  0.184
Method:                 Least Squares   F-statistic:                     119.6
Date:                Thu, 08 Oct 2026   Prob (F-statistic):           3.27e-25
Time:                        14:49:40   Log-Likelihood:                -359.38
No. Observations:                 526   AIC:                             722.8
Df Residuals:                     524   BIC:                             731.3
Df Model:                           1
Covariance Type:            nonrobust
==============================================================================
                 coef    std err          t      P>|t|      [0.025      0.975]
------------------------------------------------------------------------------
Intercept      0.5838      0.097      5.998      0.000       0.393       0.775
educ           0.0827      0.008     10.935      0.000       0.068       0.098
==============================================================================
Omnibus:                       11.804   Durbin-Watson:                   1.801
Prob(Omnibus):                  0.003   Jarque-Bera (JB):               13.811
Skew:                           0.268   Prob(JB):                      0.00100
Kurtosis:                       3.586   Cond. No.                         60.2
==============================================================================

Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.
8. What are the OLS assumptions, in plain words?
Section 2 separated the method from the model. Apart from the second, none of the conditions below is needed to compute the OLS line: the arithmetic works on any data in which x varies. They are conditions on the true model and on how the sample was drawn, and they decide whether the fitted line is a good estimate of the true one. For that we need:
- A true relationship that is linear in the coefficients. y can depend on x2 or on log x, as in the right-hand panel of Figure 3; the coefficients must enter as multipliers, with the error added on.
- Some variation in x. If every worker had the same education, the slope's denominator would be zero and there would be no slope to find.
- Nothing left in the error that moves with x. Formally \(\mathbb{E}[u_i \mid x_i] = 0\). This is the assumption that makes OLS unbiased (right on average across samples), and the one that matters most.
- Errors with the same spread at every x (homoskedasticity) and errors that are unrelated from one observation to the next. These two are not needed for unbiasedness; they are what make the usual standard errors right.
Textbooks number these differently (Wooldridge has five) but the content is the same: the Gauss-Markov assumptions, which the Gauss-Markov theorem and BLUE page states precisely. Here is what the third one looks like in numbers.
| Regression and coefficient | Alone | With other variables added |
|---|---|---|
| Birthweight (oz) on cigarettes a day: coefficient on cigs | -0.514 | -0.463 (family income added) |
| log(wage) on years of education: coefficient on educ | 0.0827 | 0.0920 (experience and tenure added) |
Mothers with higher family incomes smoke less (correlation -0.17) and, holding cigarettes fixed, have heavier babies (about 0.09 oz per $1,000). With income left out, part of its effect is carried by the cigarette coefficient, so -0.514 moves to -0.463 once income is in. The same thing happens in the wage data: the more educated workers in this 1976 sample have less experience (correlation -0.30) and slightly less tenure, both of which raise pay, so leaving them out pulls the education coefficient down from 0.092 to 0.083 (about two thirds of the gap is experience, a third tenure). In both cases leaving the variables out pulls the coefficient down: the negative coefficient becomes more negative and the positive one smaller. Lesson 13 gives the rule for the direction and the size of such a change. Neither longer regression is the final word: prenatal care is still in the birthweight error and ability is still in the wage error. Income and experience were in the data and could be added; ability is not, so the question has to be argued rather than computed. When assumption 3 is not believable, instrumental variables and natural experiments look for variation in x that is unrelated to the error. When assumption 4 fails the fix is cheap: the coefficients stay unbiased and only the standard errors need replacing with the robust version. The diagnostic testing page has the checks.
9. Common mistakes
- Treating the fitted line as the true line. \(\hat\beta_1 = 2.2\) is what these five workers give. The population slope \(\beta_1\) is what it estimates, and another sample would give another estimate. A statement about the population needs the standard error or the interval as well as the coefficient.
- Stating a result without the assumption that makes it true. In my feedback on one time-series exam, the biggest single slip on a derivation question was to state a result without the assumption behind it. The same slip costs marks in regression: "OLS is unbiased" earns little; "OLS is unbiased because nothing in the error moves with x, \(\mathbb E[u\mid x]=0\)" earns the marks.
- Dropping the units from the slope. "2.2" is not an interpretation. "£2.20 an hour per extra year of education" is. Percentage points and percent are different units; a log-wage slope of 0.0827 is about 8.3%, not 0.0827 of anything.
- Interpreting an intercept far outside the data. In the wage regression of section 4 the intercept is minus 90 cents an hour at zero years of schooling. Check whether x = 0 is in the data before reading the intercept as a prediction.
- Calling a slope an effect. The slope is a conditional comparison: workers with one more year of education earn, on average, this much more. "Education raises pay by" needs assumption 3 and an argument for it.
10. Check your understanding
Six questions, marked on the page; every option has an explanation, including the wrong ones. (Without JavaScript the explanations are shown beneath each question.)
1. Four observations: x = 0, 1, 2, 3 and y = 1, 2, 2, 5. What is the OLS slope?
0.7 is the intercept, not the slope: with the slope 1.2, the intercept is 2.5 - 1.2 × 1.5 = 0.7. The slope comes first; the intercept is found from it.
Correct. Means 1.5 and 2.5. Deviations in x: -1.5, -0.5, 0.5, 1.5; in y: -1.5, -0.5, -0.5, 2.5. Products sum to 6; squared x deviations sum to 5. Slope = 6/5 = 1.2.
1.33 is the rise over run between the first and last points, (5 - 1)/(3 - 0). That ignores the two middle points; least squares uses all four.
6 is the numerator, the sum of the products of deviations. Divide by the sum of squared x deviations, 5, to get "y per unit of x".
2. In the regression bwght = 119.77 - 0.514 × cigs (ounces), what does 119.77 mean?
The sample mean is 118.7 oz. The intercept equals the mean of y only when the mean of x is zero; here the mean of cigs is 2.1, so the intercept sits above it by 0.514 × 2.1.
That is the slope, -0.514 oz per cigarette a day. The intercept is a level (a predicted weight), the slope is a rate of change.
Correct. The intercept is the fitted value at x = 0, and non-smokers are the commonest case in this data, so it is a prediction about real mothers: 119.8 oz, about 3.4 kg.
3. A least-squares line with an intercept is fitted to five points. Four of the residuals are 1.1, -0.3, 0.5 and -0.9. What is the fifth?
Correct. The residuals of a least-squares line with an intercept sum to zero (the intercept's first-order condition). The four given sum to 0.4, so the fifth is -0.4.
Zero is the sum of all the residuals, not the value of any one of them; it is the total that the intercept forces to zero.
A sign slip. The four given residuals add to +0.4, so the fifth must be -0.4 to bring the total to zero.
You do not need the data. The intercept's first-order condition forces the residuals to sum to zero in every sample, so four residuals pin down the fifth.
4. Which quantity does ordinary least squares make as small as possible?
Perpendicular distances define total least squares, a different line that treats x and y symmetrically. OLS treats y as the thing predicted, so it uses vertical gaps.
Correct. The vertical gap at each point is the residual, actual y minus fitted y, and OLS minimises the sum of their squares: 1.60 for the five-worker line, and no other line gets lower.
That is least absolute deviations, a median-type fit with no closed-form formula. For the five workers it gives 10 + 2x, not 9.6 + 2.2x.
5. In the birthweight regression the slope on cigarettes has t = -5.7 and the R-squared is 0.023. Which reading is right?
Correct. Significance asks whether the slope could be zero; R-squared asks how much of y the line captures. With 1,388 births, half an ounce per cigarette is estimated precisely even though most of the variation in birthweight has nothing to do with smoking.
R-squared is the share of the variation in y the line accounts for, not a test of whether the slope is zero. A small share and a precisely estimated slope sit together easily in a large sample.
Significance and fit are different questions. The t-statistic grows with sample size for a fixed slope; R-squared does not, so a large sample can make a small association highly significant.
6. The true relationship between y and x is a curve. A researcher fits a straight line to a large sample by OLS. Which statement is right?
OLS is arithmetic on the sample and can be applied to any data in which x varies. Linearity is an assumption about the true model: it decides what the fitted line means, not whether the line can be computed.
Correct. OLS always returns a straight line. When the true relationship is curved, the line it settles on in a large sample is the closest straight-line approximation: for the curve of Figure 3, 1 + 0.08x², that is -0.33 + 0.8x, too low at both ends and too high in the middle.
More data makes the fitted line settle down, but it settles on a straight line (-0.33 + 0.8x for the curve of Figure 3), because a straight line is all that is being fitted. To follow the curve the model has to change, for example by regressing y on x squared.
11. Questions people search for
OLS stands for ordinary least squares, in statistics and in economics alike. It fits a straight line to data by choosing the intercept and slope that make the sum of the squared residuals (the vertical gaps between points and line) as small as possible. Ordinary means every observation counts equally; weighted least squares gives some observations more say.
With one regressor, the OLS slope is the sum of (x minus its mean) times (y minus its mean), divided by the sum of (x minus its mean) squared: the covariance of x and y divided by the variance of x. The intercept is the mean of y minus the slope times the mean of x.
In everyday use they mean the same thing. Strictly, linear regression is a model: the assumption that, in the population, y is a straight-line function of x plus an error. OLS is an estimator: a rule that computes the line from a sample by minimising the squared residuals. How well it works depends on whether the model is true.
Adding raw residuals is useless because positive and negative ones cancel. Squares and absolute values both fix that. Squares win because they make the fitting problem smooth, so calculus gives the slope and intercept as formulas, and because fitting a constant by least squares returns the mean. The cost is that one outlier can tilt the line.
The intercept is the predicted value of y when x is zero. It means something when x = 0 is a real case in the data: regress birthweight on cigarettes a day and the intercept, 119.8 ounces, is the predicted weight of a non-smoker's baby. When x = 0 is impossible, the intercept only anchors the line.
12. Where next
- The course lessons that go with this page: lesson 9, fitting the OLS line by hand, lesson 10, residuals, fit and R-squared, and lesson 11, reading regression output.
- Lesson 12: multiple regression and holding other things fixed, where the 0.0827 becomes 0.0920 with experience and tenure in the model.
- The OLS estimator in matrix form: normal equations, unbiasedness and the variance formula.
- The Gauss-Markov theorem and BLUE: when OLS is the best linear unbiased estimator.
- How to read regression output, R-squared and adjusted R-squared, and logs and elasticities (why 0.0827 reads as 8.3%, and as 8.6% exactly).
- Correlation versus causation, diagnostic tests for the linear model and instrumental variables, for when assumption 3 is in doubt.
- Expectation, variance and covariance (lesson 3: the slope formula's ingredients) and the law of large numbers (lesson 4), which is why OLS is consistent.
Send me your regression: module, output and deadline
I tutor econometrics one-to-one, from a first regression through to endogeneity, panel data and time series. Bring the output you are stuck on and we will read it together in the free 30-minute consultation.
Book a free 30-minute consultation Econometrics tutor: how it works
You can also watch free worked videos on the @unientryTMUA YouTube channel (regression, the Gauss-Markov theorem, t-tests and more) or download free econometrics lecture notes.
Data and figures. Five-worker and outlier examples: illustrative data. Birthweight and pay: Wooldridge, Introductory Econometrics: A Modern Approach, data sets BWGHT (1,388 births, 1988 National Health Interview Survey) and WAGE1 (526 workers, 1976 Current Population Survey), loaded with bcuse in Stata and with the wooldridge package in R and in Python; results quoted, data not republished. Premier League: match results from openfootball/england (CC0), with the 2023/24 deductions for Everton (8) and Nottingham Forest (4) applied. Figures drawn for this page from these sources.