
UK inflation, recorded each month since 1989, is a time series: a single history whose neighbouring values resemble each other, unlike a random sample. These notes show what must be assumed of the process behind such a history for it to teach us anything, and how the dependence of the present on the past is measured.
1. Process and realisation
The first idea separates the mechanism that produces a series from the numbers it produced.
Definition: process and realisation
A time series process \(Y_t\), \(t = \dots, -1, 0, 1, 2, \dots\), is a collection of random variables, one for each date, with their joint distribution. A realisation (the data, or sample path) is the sequence of numbers observed, \(y_1, y_2, \dots, y_T\): one value of each \(Y_t\) over the \(T\) dates of the sample.
Remarks. Intuitively, the process governs the probabilities of the paths the series could take, and the data are the one path that history produced. The process is not the data: had history run again, the same process would have given a different path. Capital letters mark random variables and lower-case letters observed numbers; books use other letters, and the choice is cosmetic.
A simulation shows the difference, because there we set the process ourselves. In Figure 1 each value is 0.1, plus 0.4 times the previous value, plus a fresh shock drawn independently from the standard normal distribution: \(Y_t = 0.1 + 0.4\,Y_{t-1} + \varepsilon_t\), started at \(Y_0 = 0\). This rule is a first-order autoregression, or AR(1). If its mean \(\mu\) is the same at every date, taking expectations gives \(\mu = 0.1 + 0.4\mu\), so \(\mu = 0.1/0.6 = 0.167\).
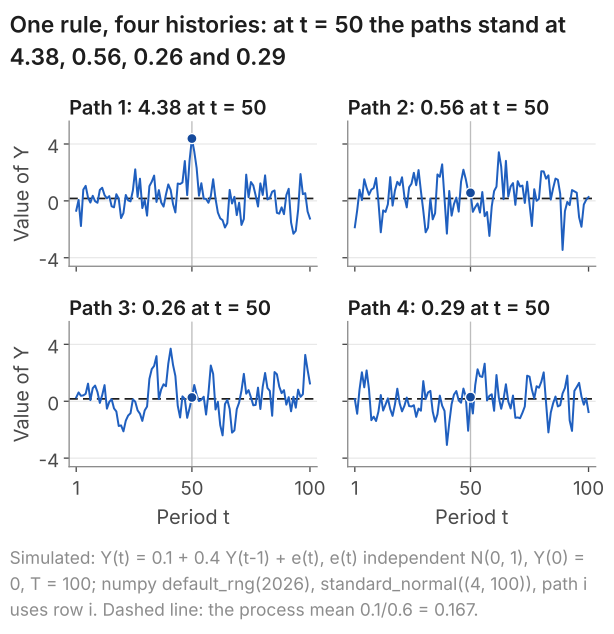
With real data we see one panel and never the rule: the aim is to infer the process from that one path. Lesson 21 develops the process and the data and one rule, four histories.
What students say
“Nicky is an excellent econometrics tutor. He explains complex concepts clearly and makes them much easier to understand.”
“I was completely lost in my economics class, and then I started working Nicky and he totally saved me. He was excellent at explaining the material and extremely accommodating to meet with me many times despite us being in different time zones! Highly recommend working with Nicky!”
“Nicky is a very good and thorough teacher. He has excellent knowledge of econometrics and takes the time to work through your questions. Highly recommended!”
“Really great tutor! Encouraging, knowledgeable, friendly”
“Very good lesson, Nicky is very helpful.”
“Very helpful and clear.”
“I gather it was very useful, thank you!”
“Fantastic!”
2. Why an observed value can still be treated as random
It can seem odd to call observed data random: UK inflation for September 2016 is a published number that will not change. Before that month, though, the rate was uncertain, and each range of values had some probability. The process describes those probabilities before the date; the realisation records the outcome.
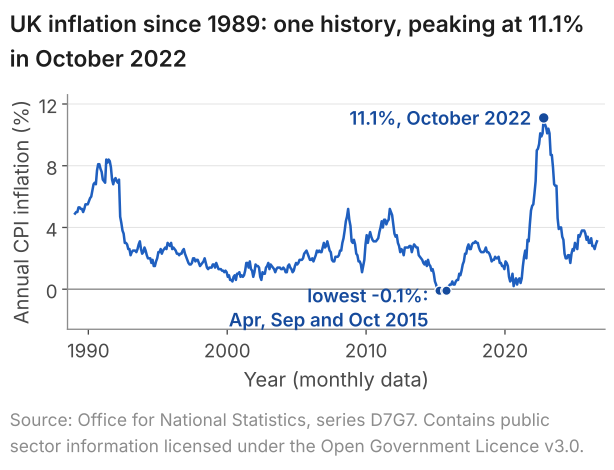
The 452 numbers are one draw from the joint distribution of \(Y_1, \dots, Y_{452}\), so a forecast or a test built from them is a statement about the paths the process could have produced. Lesson 21 replays this history 10,000 times from a simple rule fitted to it. Only 24 replays ever reach 11.1%, and the median replay spends 21 months below zero, against 3 in the actual history. That is evidence about the simple rule, not a measure of how unlikely 2022 was.
3. What real series show
A graph against time comes first, because what it shows points to what a model must describe. Table 1 lists five series from lesson 22, each with its feature and one number.
| Series | Feature (lesson 22 section) | The number behind it |
|---|---|---|
| UK real GDP, quarterly, 1955 Q1 to 2026 Q2, seasonally adjusted | Trend: a persistent change in the level | 149.4 to 744.5 billion pounds, 4.98 times as much |
| UK GDP growth, quarterly, 1984 Q1 to 2026 Q2 | Outliers: values far from the rest | 2020 Q2: -19.9%, about 32 standard deviations below the 1984 to 2019 mean |
| UK retail sales, monthly, 1996 to 2025, not seasonally adjusted | Seasonality: a pattern that repeats each year | December 25.8% above its year's mean on average; the top month in all 30 years |
| UK unemployment rate, monthly, 1971 to 2026, seasonally adjusted | Persistence: long spells on one side of the mean | Same side of its mean as the month before in 660 of 664 steps (overlapping three-month averages add to this) |
| IBM stock returns (US), monthly, 1926 to 2003 | Volatility: a spread that changes over time | Standard deviation 4.9% in 1936 to 1945, 10.6% in 1996 to 2003 |
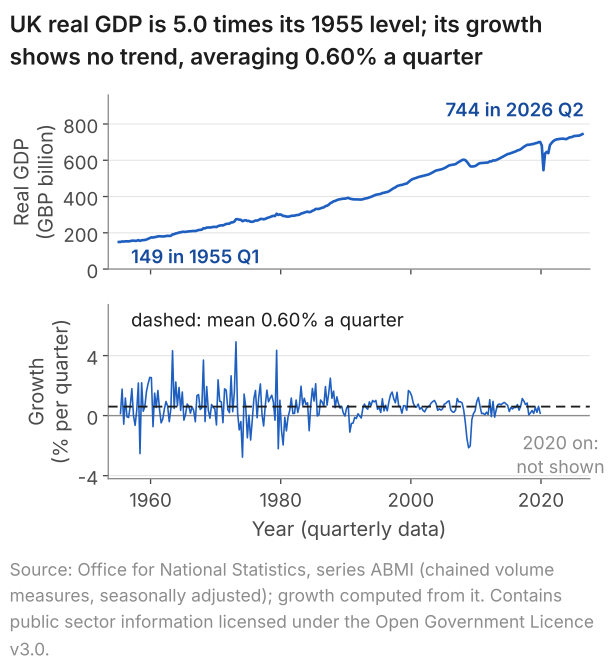
A level that rises about fivefold over 71 years is not consistent with a stationary process, whose mean is the same at every date. Growth, \(100 \times (\text{GDP}_t/\text{GDP}_{t-1} - 1)\) per cent per quarter, moves around 0.60% with no trend, so its mean is consistent with one. Hence the GDP examples on these pages use growth, which lesson 22 builds from the level. The spread of growth does not look constant, though: the standard deviation is 1.26 over 1955 Q2 to 1983 Q4 and 0.64 over 1984 Q1 to 2019 Q4, the main sample from lesson 23 on.
4. Stationarity
Stationarity, with dependence that fades between distant dates, is the stability that lets one path teach us about a process. If the mean or the variance changed at every date, each date would supply one observation of its own distribution, and a longer series would add no further observation of any of them.
Definition: stationarity (weak, or covariance, stationarity)
A process \(Y_t\) is stationary if, for every date \(t\) and every lag \(k\),
$$ \begin{aligned} E(Y_t) &= \mu , \\ \operatorname{Var}(Y_t) &= \gamma(0) < \infty , \\ \operatorname{Cov}(Y_t, Y_{t-k}) &= \gamma(k) . \end{aligned} $$None of \(\mu\), \(\gamma(0)\) and \(\gamma(k)\) depends on the date \(t\); \(\gamma(k)\) may change with the lag \(k\).
Remarks. Intuitively, a stationary process keeps its behaviour over time: its centre, its spread and the link between values \(k\) periods apart are the same whatever the date. Stationarity belongs to the process; data can only look stationary, or be consistent with it. It is an assumption, and it may not hold.
Stationary does not mean "no trend". A random walk adds each period's shock to the last value, \(Y_t = Y_{t-1} + \varepsilon_t\), with uncorrelated shocks of mean zero and variance \(\sigma^2\). From a fixed start \(y_0\), \(Y_t = y_0 + \varepsilon_1 + \dots + \varepsilon_t\). The variance of a sum of uncorrelated variables is the sum of their variances (lesson 3), so \(\operatorname{Var}(Y_t) = t\sigma^2\). The mean stays at \(y_0\), so there is no trend. The variance, though, is finite at every date but grows in proportion to the time since the start: with \(\sigma^2 = 1\), it is 25 at \(t = 25\) and 100 at \(t = 100\). The variance condition fails, and so does the third, as \(\operatorname{Cov}(Y_t, Y_{t-k}) = (t-k)\sigma^2\) depends on the date: a random walk is not stationary. Lesson 24 shows random walks fanning out and what differencing does.
5. White noise, and how it differs from stationarity
White noise is the simplest stationary process and the shock from which time series models are built.
Definition: white noise
A process \(\varepsilon_t\) is white noise, written \(\varepsilon_t \sim \text{WN}(\sigma^2)\), if for every date \(t\)
$$ \begin{aligned} E(\varepsilon_t) &= 0 , \\ \operatorname{Var}(\varepsilon_t) &= \sigma^2 < \infty , \\ \operatorname{Cov}(\varepsilon_t, \varepsilon_{t-k}) &= 0 \ \text{ for every } k \ge 1 . \end{aligned} $$Remarks. Intuitively, white noise fluctuates around zero with a constant spread, and its past values are uncorrelated with its future ones, so no linear forecast from the past does better than zero. It meets all three conditions of stationarity, so it is stationary. The reverse is false: stationarity and white noise are not the same thing.
Independent and identically distributed (i.i.d.) shocks with mean zero and finite variance are white noise, and white noise is stationary; neither statement reverses. Table 2 gives an example for each class that is not in the narrower class above it.
| Class | What it requires | In this class, not the one above |
|---|---|---|
| i.i.d. normal, mean zero | Independent draws from one normal distribution | The shocks of Figure 1: independent N(0, 1) draws |
| i.i.d., mean zero, finite variance | Independent draws from one distribution of any shape | Independent draws from the uniform distribution on -1 to 1: variance 1/3, not normal |
| White noise | Mean zero, constant finite variance, no correlation between dates | A shock whose size moves with the last shock's size, while its sign is unrelated to the past. IBM's monthly returns, 1926 to 2003, look like this: correlation 0.035 between successive months, inside ±0.064, the approximate 95% range for independent data, but 0.208 between successive squared deviations |
| Stationary | Constant mean and finite variance; autocovariance depends on the lag only | The rule of Figure 1, run from the distant past: mean 0.167, correlation 0.4 between successive values |
| Not stationary | At least one condition fails | A random walk: variance \(t\sigma^2\) at date \(t\) |
6. Autocovariance and autocorrelation: measuring memory
A process has memory when its value today depends on its own past values or past shocks. The autocovariance and the autocorrelation measure the linear part of that dependence, one lag at a time.
Definition: autocovariance and autocorrelation
For a stationary process \(Y_t\) and each lag \(k = 0, 1, 2, \dots\), the autocovariance is the covariance between values \(k\) periods apart, and the autocorrelation is that covariance divided by the variance:
$$ \begin{aligned} \gamma(k) &= \operatorname{Cov}(Y_t, Y_{t-k}) , \\ \rho(k) &= \gamma(k)/\gamma(0) . \end{aligned} $$Remarks. Stationarity makes both depend on the lag alone. Since \(Y_t\) and \(Y_{t-k}\) both have variance \(\gamma(0)\), \(\rho(k)\) is their ordinary correlation. It has no units and lies between -1 and 1; \(\gamma(k)\) is in the squared units of \(Y\). \(\rho(k)\) belongs to the process; it is not computed from data.
In data, \(\rho(k)\) is estimated by the sample autocorrelation \(r(k)\): the sum of products of deviations from the sample mean \(k\) periods apart, divided by the sum of squared deviations. Slides and software write \(\hat\rho(k)\) or "AC". Lesson 23 builds the formula and computes \(r(1)\) by hand.
A correlogram plots \(r(k)\) against \(k\). If the observations are independent with constant variance, \(r(k)\) at one lag is approximately normal with mean 0 and variance \(1/T\) in a large sample. Hence it lies within \(\pm 1.96/\sqrt{T}\) in about 95% of samples, and a bar outside that band is evidence against zero autocorrelation at that lag, at the 5% level. For \(T = 144\) the band is \(\pm 1.96/12 = \pm 0.163\).
Figure 4 uses the main GDP sample, 1984 Q1 to 2019 Q4. Two pandemic quarters would dominate every statistic: adding the quarters from 2020 Q1 to 2026 Q2 turns \(r(1)\) from 0.56 into -0.27 and the standard deviation from 0.64 into 2.18.
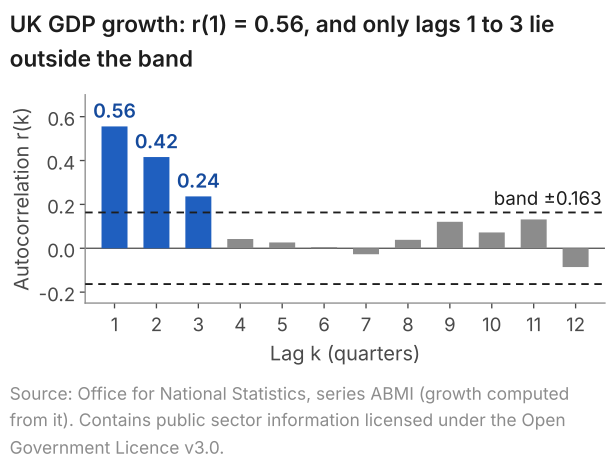
In these 144 quarters the bars at lags 1 to 3 give evidence against zero autocorrelation, declining from 0.556 to 0.237. Each bar is a test at one lag. With independent data a little under one bar in twenty falls outside the band, and in 10,000 simulated independent series of this length at least one of twelve bars did in 40.3% of them (lesson 23). The Q-test takes several lags together, and lesson 23 reads this correlogram in full.
7. The first simple processes
Simple models build memory out of white-noise shocks in different ways, and each leaves its own pattern in the autocorrelations (Table 3).
| Process and rule | How long a shock lasts | Autocorrelations \(\rho(k)\) |
|---|---|---|
| White noise: \(Y_t = \varepsilon_t\) | Its own period only | 0 for every \(k \ge 1\) |
| MA(1), moving average: \(Y_t = \alpha + \varepsilon_t + \theta\,\varepsilon_{t-1}\) | Two periods: its own and the next | \(\rho(1) = \theta/(1+\theta^2)\), at most 0.5 in size; 0 from lag 2 on |
| AR(1), autoregression, \(|\phi| < 1\): \(Y_t = \alpha + \phi\,Y_{t-1} + \varepsilon_t\) | For ever, with weight \(\phi^k\) after \(k\) periods | \(\phi^k\): a geometric decline, alternating in sign when \(\phi < 0\) |
| Random walk: \(Y_t = Y_{t-1} + \varepsilon_t\) | For ever, at full weight | Not stationary: no \(\rho(k)\) that depends on the lag alone |
With \(\theta = 0.9\) an MA(1) has \(\rho(1) = 0.9/1.81 = 0.497\) and zero beyond lag 1; with \(\phi = 0.9\) an AR(1) still has \(\rho(10) = 0.35\). An AR(1) with \(|\phi| < 1\) that has run from the distant past is stationary, with mean \(\alpha/(1-\phi)\), not \(\alpha\). On real data, the AR(1) fitted by OLS to UK GDP growth, 1984 Q1 to 2015 Q4, has \(\hat\phi = 0.56\): the expected gap from the mean halves in about 1.2 quarters (lesson 25). The simple rule fitted by OLS to UK inflation since 1989 has \(\hat\phi = 0.984\), and its expected gap halves in about 43 months.
8. Common mistakes
- "Stationary means no trend." A random walk whose shocks have mean zero has no trend and is not stationary: from a fixed start its variance at date \(t\) is \(t\sigma^2\).
- "Stationary means white noise." The rule of Figure 1 is stationary when run from the distant past, yet successive values have correlation 0.4.
- "White noise means independent." Successive monthly IBM returns have a correlation of 0.035, consistent with white noise, but their squared deviations have 0.208, far outside ±0.064: evidence that the returns are not independent.
- Calling a series non-stationary without saying why. Name the condition that seems to fail and the evidence, such as the rise of UK GDP from 149.4 to 744.5 billion pounds.
- "A bar outside the band identifies the model." It is evidence against zero autocorrelation at that lag. An AR(1) with \(\phi = 0.556\) would have \(\rho(2) = 0.309\), while \(r(2) = 0.416\): other models remain candidates.
9. Check your understanding
Five questions, marked on the page; every option has an explanation, including the wrong ones. (Without JavaScript the explanations are shown beneath each question.)
1. A random walk starts at \(Y_0 = 0\) and adds a white-noise shock with variance 1 each period: \(Y_t = Y_{t-1} + \varepsilon_t\). Is the process stationary?
Correct. From \(Y_0 = 0\), \(Y_t = \varepsilon_1 + \dots + \varepsilon_t\), a sum of \(t\) uncorrelated shocks with variance 1 each, so \(\operatorname{Var}(Y_t) = t\): 25 at \(t = 25\) and 100 at \(t = 100\). A stationary process has the same finite variance at every date. The autocovariance condition fails too.
A trending mean is the failure seen in the level of GDP, so it comes to mind first. Here every shock has mean zero, so \(E(Y_t) = 0\) at every date and the mean condition holds. What fails is the variance, which is \(t\) at date \(t\).
The shocks are white noise, but the walk adds them up, and the variance of a sum of \(t\) uncorrelated shocks is \(t\) times theirs: 100 by \(t = 100\). A process built from stationary shocks need not be stationary.
2. Monthly returns on IBM stock, 1926 to 2003 (\(T = 936\)), measured from their mean: the correlation between successive months is 0.035. For the squares of these deviations it is 0.208. For independent data the approximate 95% range is ±0.064. What do these numbers indicate?
Zero correlation is not independence. If the returns were independent, their squared deviations would be uncorrelated too, and 0.208 is more than three times 0.064, the edge of the range.
Correct. 0.035 lies inside ±0.064, so successive returns show no evidence of correlation, as white noise requires. But 0.208 for the squared deviations lies far outside: large moves follow large moves, which independent returns would not do.
White noise restricts only the correlations of the values themselves, with their mean and variance. Correlated squares are allowed, so 0.208 is evidence against independence, not against white noise.
3. UK real GDP rose from 149.4 billion pounds in 1955 Q1 to 744.5 billion in 2026 Q2. Its quarterly growth from 1955 Q2 to 2019 Q4 moves around a mean of 0.60% with no trend. Why do the GDP examples on this page model growth rather than the level?
Growth does not look like white noise: over 1984 Q1 to 2019 Q4 its sample autocorrelation at lag 1 is 0.556, far outside ±0.163. Over those quarters it is consistent with a stationary process, which is a weaker property than white noise.
Correct. A stationary process has the same mean at every date. The level ends 4.98 times as high as it starts, so no single mean describes it; growth moves around 0.60% a quarter with no trend, so its mean is consistent with a stationary process.
Recessions stay in the growth series as negative quarters: 2008 Q4 is -2.1% and 2020 Q2 is -19.9%. Taking growth removes the trend in the level, not the recessions.
4. Figure 1 shows four paths of 100 periods from one rule, \(Y_t = 0.1 + 0.4\,Y_{t-1} + \varepsilon_t\), all started at 0. Their means are 0.25, 0.34, 0.32 and 0.07; the process mean is 0.167. What explains the differences between the four means?
One rule produced all four, with the same intercept and the same coefficient; only the shocks differ. Different realisations do not imply different processes.
A path mean comes from the 100 values of one realisation, so it differs from the process mean by chance. For these paths its standard deviation is about 0.17, so 0.07, which is 0.10 below 0.167, lies within one standard deviation of it.
Correct. The same process gives a different path each time its history is replayed, and a path mean is a statistic of one path. For paths of 100 periods started at 0 its standard deviation is about 0.17, and all four means lie within about one standard deviation of 0.167.
5. The correlogram of UK GDP growth, 1984 Q1 to 2019 Q4 (\(T = 144\)), has \(r(1) = 0.556\), \(r(2) = 0.416\), \(r(3) = 0.237\), and \(r(4)\) to \(r(12)\) between -0.086 and 0.131. The band is \(\pm 1.96/\sqrt{144} = \pm 0.163\). What follows at the 5% level?
Correct. \(r(1)\), \(r(2)\) and \(r(3)\) lie outside ±0.163, so each is evidence against zero autocorrelation at its lag; \(r(4)\) to \(r(12)\) lie inside. The Q-test on lags 1 to 8 agrees: \(Q(8) = 80.08\), p below 0.0005.
A correlogram shows dependence; it does not identify the process. An AR(1) with \(\phi = 0.556\) would have \(\rho(2) = 0.556^2 = 0.309\), below the sample's 0.416: an AR(1) is one candidate, and an AR(2) or an ARMA(1,1) are others.
\(r(1) = 0.556\) is an estimate from these 144 quarters; another history of the same length would give another value. \(\rho(1)\) belongs to the process and stays unknown; the bar is evidence that it is not zero.
10. Four questions about time series econometrics
Time series econometrics provides methods for data recorded at successive dates, such as 452 months of UK inflation. It treats the data as one realisation of a process, asks whether that process is stable over time (stationary) and models how each value depends on the past, so that one history can support estimates and forecasts.
A process is stationary when its mean and its finite variance are the same at every date, and the covariance between two values depends only on how far apart they are. A random walk is not: from a fixed start its variance at date t is t times the shock variance, 100 at t = 100 with unit shocks.
White noise is a process with mean zero, a constant finite variance and no correlation between its values at different dates. It is the shock from which AR and MA models are built. It need not be independent: successive monthly IBM returns have a correlation of 0.035, while their squared deviations have one of 0.208.
White noise is a special case of a stationary process: besides a constant mean and variance and autocovariances that depend only on the lag, it has mean zero and no correlation between different dates. So it is stationary, but a stationary process need not be white noise: a stationary AR(1) with coefficient 0.4 has correlation 0.4 at lag 1.
11. Where next
- The course lessons that teach these ideas slowly: lesson 21 (process and realisation), lesson 22 (reading a graph), lesson 23 (the correlogram), lesson 24 (stationarity and random walks) and lesson 25 (AR(1) models and forecasting).
- How to read a correlogram: the bands, the Q-test and residual checks.
- AR, MA, ARMA and ARIMA models, and serial correlation in regression errors.
- Part 2 of these notes: the Wold decomposition, the lag operator, prediction and seasonality.
- The full module notes and the companion video playlist.
Send me your module outline and the series you are modelling
I tutor time series econometrics one-to-one. Bring the question you are stuck on and we will work through it in the free 30-minute consultation.
Book a free 30-minute consultation Econometrics tutor: how it works
Data and simulation. Inflation: Source: Office for National Statistics, series D7G7. Contains public sector information licensed under the Open Government Licence v3.0. GDP: Source: Office for National Statistics, series ABMI (growth computed from ABMI), as published in September 2026. Contains public sector information licensed under the Open Government Licence v3.0. Retail sales: Source: Office for National Statistics, series J5AH. Contains public sector information licensed under the Open Government Licence v3.0. Unemployment: Source: Office for National Statistics, series MGSX. Contains public sector information licensed under the Open Government Licence v3.0. The ONS series were retrieved on 10 October 2026. IBM returns: Source: Tsay (2005), Analysis of Financial Time Series, 2nd edition (data from CRSP), via the R package FinTS. Results only; the data are not republished. Figure 1, simulated: Y(t) = 0.1 + 0.4 Y(t-1) + e(t), e(t) independent N(0, 1), Y(0) = 0, T = 100; numpy default_rng(2026), standard_normal((4, 100)), path i uses row i. Adapted from my lecture notes for Time Series Econometrics (ECON30401) at the University of Manchester.