
Modelling a time series starts from how today's value is related to the value one, two or more periods earlier. Sample autocorrelations estimate this lag by lag from one history, so each carries sampling error. This page shows how to read a correlogram: its band, the Q-test, residual correlograms and the shapes of simple models.
1. Population and sample autocorrelations
A correlogram estimates a property of a process from one observed history, so two quantities have to be kept apart. The process \(Y_t\) is a random variable at each date \(t\); the data \(y_1, \dots, y_T\) are the \(T\) numbers we observe, one path of the process. Lesson 23 builds both step by step.
Definition: autocorrelation and sample autocorrelation
For a stationary process, whose mean, variance and autocovariances do not change over time, the autocorrelation at lag \(k\) is \(\rho(k) = \gamma(k)/\gamma(0)\), where \(\gamma(k) = \operatorname{Cov}(Y_t, Y_{t-k})\) and \(\gamma(0)\) is the variance. Its estimate from \(T\) observations with mean \(\bar y\) is
$$ r(k) = \frac{\sum_{t=k+1}^{T}(y_t-\bar y)(y_{t-k}-\bar y)}{\sum_{t=1}^{T}(y_t-\bar y)^2} . $$In words: add up the products of deviations from the mean for values \(k\) periods apart, and divide by the sum of squared deviations.
Remarks. Intuitively, \(\rho(k)\) is the correlation between the process now and \(k\) periods earlier; \(r(k)\) measures it in one history. The two are not the same: another history of the same length would give another \(r(k)\), while \(\rho(k)\) stays fixed. A correlogram plots \(r(k)\).
The numerator starts at \(t = k+1\), the first date with a value \(k\) periods earlier in the sample, so lag \(k\) uses \(T-k\) products; numerator and denominator are in the same squared units, so \(r(k)\) has none (lesson 23 explains each part). The examples use UK GDP growth over the 144 quarters from 1984 Q1 to 2019 Q4, where \(r(1) = 0.556\); the quarters from 2020 are left out because two pandemic quarters would dominate every statistic (with the quarters to 2026 Q2 included, \(r(1)\) is -0.27: lesson 22). Books and software write \(\hat\rho(k)\), "AC" or "ACF" for \(r(k)\); the choice of letters is cosmetic.
What students say
“Nicky is an excellent econometrics tutor. He explains complex concepts clearly and makes them much easier to understand.”
“I was completely lost in my economics class, and then I started working Nicky and he totally saved me. He was excellent at explaining the material and extremely accommodating to meet with me many times despite us being in different time zones! Highly recommend working with Nicky!”
“Nicky is a very good and thorough teacher. He has excellent knowledge of econometrics and takes the time to work through your questions. Highly recommended!”
“Really great tutor! Encouraging, knowledgeable, friendly”
“Very good lesson, Nicky is very helpful.”
“Very helpful and clear.”
“I gather it was very useful, thank you!”
“Fantastic!”
2. What a correlogram shows
A correlogram sets the sample autocorrelations side by side, one bar per lag, to show a series' dependence in one picture. The horizontal axis is the lag \(k\), in the series' own time unit, from 1 to a maximum lag \(m\) chosen by the analyst. The height of each bar is \(r(k)\), between -1 and 1, read like any correlation coefficient. The dashed lines either side of zero are the band of section 3. A plot or a printout may also show lag 0, where the autocorrelation is 1 by definition (a series is perfectly correlated with itself), so that bar carries no information; both printouts in section 5 list it. A printed correlogram may come with a table, one row per lag:
| Column | What it holds |
|---|---|
| AC | The sample autocorrelation \(r(k)\). |
| PAC | The partial autocorrelation at lag \(k\) (section 8). |
| Q | The Ljung-Box statistic for lags 1 to \(k\) together (section 4); row \(k\) tests those lags, not the whole table. |
| Prob | The p-value of that Q. |
3. Testing one autocorrelation: two kinds of band
A bar is an estimate, so deciding whether it lies further from zero than sampling variation alone would put it calls for a test, at one lag, of \(H_0: \rho(k) = 0\) against \(H_1: \rho(k) \neq 0\). The band is the test's rejection boundary at the 5% level, and the two kinds of band differ in what the null assumes about the other lags.
The constant band. Suppose the observations are independent with a constant variance, so that every autocorrelation is zero. Then \(r(k)\) is in essence an average of \(T-k\) uncorrelated products of deviations, so in a large sample it is approximately normal with mean 0 and a variance of \(1/T\), falling with the sample size as the variance of a sample mean does. A normal variable lies within 1.96 standard deviations of its mean with probability 0.95. Hence \(r(k)\) lies inside \(\pm 1.96/\sqrt{T}\) with probability about 0.95, and a bar outside it is evidence against zero autocorrelation at that lag at the 5% level, though not a sign of any particular model. For \(T = 144\) the band is \(\pm 1.96/12 = \pm 0.163\); some programs draw \(\pm 2/\sqrt{T}\), which is \(\pm 0.167\).
The band that widens with the lag. Once a bar is far outside, independence has already been rejected: for GDP growth \(r(1) = 0.556\) is more than three times 0.163. Bartlett's band asks at each lag \(k\) whether the autocorrelations could be zero from lag \(k\) on, whatever they are at lags 1 to \(k-1\): the null that the process is a moving average of order \(k-1\), MA(\(k-1\)), with independent shocks. Under it, in a large sample, \(r(k)\) is approximately normal with mean 0 and variance \(\bigl(1 + 2\sum_{j=1}^{k-1}\rho(j)^2\bigr)/T\). That exceeds \(1/T\) because dependence at the shorter lags makes the products in \(r(k)\) positively correlated, and an average of positively correlated terms varies more. The band puts \(r(j)\) in place of \(\rho(j)\):
$$ \pm 1.96\sqrt{\frac{1 + 2\sum_{j=1}^{k-1} r(j)^2}{T}} . $$In words: the constant band, stretched by the square root of one plus twice the sum of the squared autocorrelations at the shorter lags.
At lag 1 the two bands coincide. At lag 2, with \(r(1) = 0.556\), Bartlett's band is
$$ \begin{aligned} &1.96\sqrt{(1 + 2 \times 0.556^2)/144}\\ &= 1.96\sqrt{1.618/144} = 0.208 . \end{aligned} $$Figure 1 draws the correlogram of GDP growth with each band.
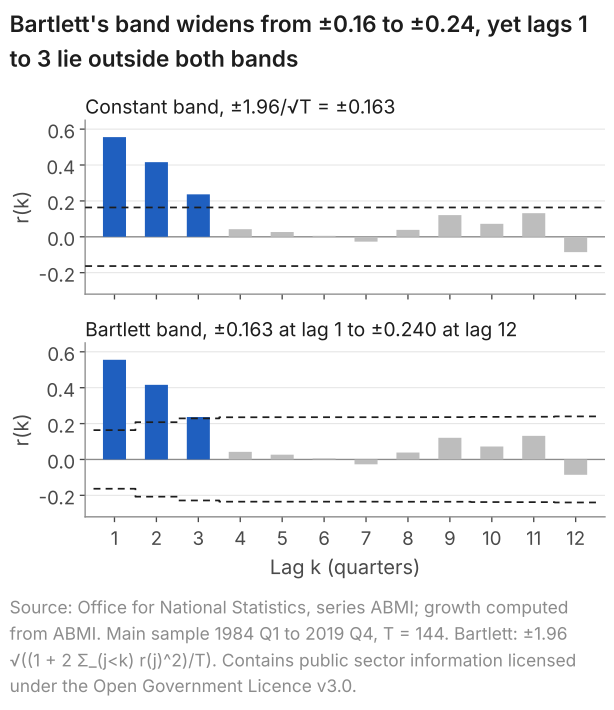
At lag 3 the margin under Bartlett's band is narrow: 0.237 against 0.229. The constant band asks whether the series could be independent; Bartlett's asks at which lag the autocorrelations could stop, the question behind choosing the order of a moving average (section 7). Programs differ in the band they draw, \(\pm 1.96/\sqrt{T}\), \(\pm 2/\sqrt{T}\) or Bartlett's, so check which one an output shows. Every other correlogram on this page draws \(\pm 1.96/\sqrt{T}\).
4. The Q-test: several lags at once
The Q-test checks several lags together, against the null that the first \(m\) autocorrelations are all zero:
$$ \begin{aligned} &H_0:\ \rho(1) = \rho(2) = \dots = \rho(m) = 0,\\ &H_1:\ \text{at least one of them is not zero.} \end{aligned} $$The Ljung-Box statistic puts the first \(m\) sample autocorrelations into one number:
$$ Q = T(T+2)\sum_{k=1}^{m}\frac{r(k)^2}{T-k} . $$In words: square each of the first \(m\) autocorrelations, weight it by \((T+2)/(T-k)\), add them up and multiply by \(T\).
Squaring stops positive and negative autocorrelations from cancelling. Under independence \(r(k)\) has variance of about \(1/T\), so \(T\,r(k)^2\) is approximately the square of a standard normal variable. The weights \((T+2)/(T-k)\), a little above 1 (146/136 = 1.07 at lag 8), replace \(1/T\) by \((T-k)/(T(T+2))\), a closer figure for that variance when \(T\) is moderate; the older Box-Pierce statistic, \(T\sum_{k=1}^{m} r(k)^2\), leaves them out. In a large sample of independent observations the \(r(k)\) at different lags are approximately independent normal variables, and a sum of \(m\) squared independent standard normal variables follows the chi-square distribution with \(m\) degrees of freedom. Hence \(Q\) is approximately \(\chi^2_m\) when the observations are independent, and the test rejects at the 5% level when \(Q\) exceeds the 95th percentile of \(\chi^2_m\), 15.51 for \(m = 8\). The p-value is the probability of a \(Q\) at least as large as the one observed if \(H_0\) is true, not the probability that \(H_0\) is true. On the residuals of a model with \(p\) autoregressive and \(q\) moving-average terms the degrees of freedom are \(m - p - q\) (section 6).
Reading the bars one at a time is not a 5% test of this null. For independent normal observations with \(T = 144\), each bar falls outside the band with probability a little under 0.05 (4.8% at lag 1, 4.0% at lag 12), yet in 10,000 simulated series of that kind at least one of the twelve bars fell outside in 40.3% of them (lesson 23). In the same series the Ljung-Box \(Q(12)\) rejected at the 5% level in 5.9% and \(Q(8)\) in 5.4%, close to the stated size and a little above it at twelve lags; Box-Pierce rejected in 4.2% and 4.4%, below it.
For GDP growth with \(m = 8\), \(T(T+2) = 144 \times 146 = 21{,}024\), and the eight terms \(r(k)^2/(T-k)\), from the unrounded autocorrelations, add to 0.00380875 (carried to six significant figures), so
$$ Q = 21{,}024 \times 0.00380875 = 80.08 , $$of which lags 1 to 3 supply 79.35. That is far above 15.51, with a p-value below 0.0005, so we reject the null that the first eight autocorrelations are all zero; Box-Pierce gives 78.12 and the same verdict. The test does not say which lags differ from zero or which model fits. A p-value above 0.05 would have meant "do not reject", which is not evidence that the autocorrelations are zero.
5. Example: UK GDP growth
This section reads one correlogram from start to finish: UK GDP growth, the quarter-on-quarter change in real GDP in per cent, 1984 Q1 to 2019 Q4. The table gives \(r(1)\) to \(r(8)\) against the constant band.
| Lag k | r(k) | Outside ±0.163? |
|---|---|---|
| 1 | 0.556 | Yes |
| 2 | 0.416 | Yes |
| 3 | 0.237 | Yes |
| 4 | 0.042 | No |
| 5 | 0.027 | No |
| 6 | 0.005 | No |
| 7 | -0.027 | No |
| 8 | 0.039 | No |
T = 144; band ±1.96/√144 = ±0.163. Ljung-Box Q(8) = 80.08 (from the unrounded autocorrelations) on 8 degrees of freedom, p-value below 0.0005.
The code reads uk-gdp-growth.csv (columns quarter, gdp and growth). Download it and save it in your working folder first.
R: the code
# UK GDP growth (% per quarter), 1984 Q1 to 2019 Q4: autocorrelations and the Ljung-Box Q
gdp <- read.csv("uk-gdp-growth.csv")
# full-precision growth from gdp (the file's growth column has 4 decimals)
gdp$growth <- c(NA, 100 * (gdp$gdp[-1] / head(gdp$gdp, -1) - 1))
g <- gdp$growth[gdp$quarter >= "1984Q1" & gdp$quarter <= "2019Q4"]
length(g)
acf(g, lag.max = 8, plot = FALSE)
Box.test(g, lag = 8, type = "Ljung-Box")
R: what it prints
> # UK GDP growth (% per quarter), 1984 Q1 to 2019 Q4: autocorrelations and the Ljung-Box Q
> gdp <- read.csv("uk-gdp-growth.csv")
> # full-precision growth from gdp (the file's growth column has 4 decimals)
> gdp$growth <- c(NA, 100 * (gdp$gdp[-1] / head(gdp$gdp, -1) - 1))
> g <- gdp$growth[gdp$quarter >= "1984Q1" & gdp$quarter <= "2019Q4"]
> length(g)
[1] 144
> acf(g, lag.max = 8, plot = FALSE)

Autocorrelations of series ‘g’, by lag

     0      1      2      3      4      5      6      7      8
 1.000  0.556  0.416  0.237  0.042  0.027  0.005 -0.027  0.039
> Box.test(g, lag = 8, type = "Ljung-Box")

	Box-Ljung test

data:  g
X-squared = 80.075, df = 8, p-value = 4.718e-14
Python: the code
import pandas as pd
from statsmodels.stats.diagnostic import acorr_ljungbox
from statsmodels.tsa.stattools import acf

# UK GDP growth (% per quarter), 1984 Q1 to 2019 Q4: autocorrelations and the Ljung-Box Q
gdp = pd.read_csv("uk-gdp-growth.csv")
# full-precision growth from gdp (the file's growth column has 4 decimals)
gdp["growth"] = 100 * gdp["gdp"].pct_change()
g = gdp.loc[gdp["quarter"].between("1984Q1", "2019Q4"), "growth"]
print("T =", len(g))
print(acf(g, nlags=8).round(3))  # lags 0 to 8
print(acorr_ljungbox(g, lags=[8]))
Python: what it prints
T = 144
[ 1.     0.556  0.416  0.237  0.042  0.027  0.005 -0.027  0.039]
     lb_stat     lb_pvalue
8  80.075065  4.721701e-14
Both printouts list lags 0 to 8 (lag 0 is 1 by definition) and the Ljung-Box statistic, 80.075 on 8 degrees of freedom, with p-values of 4.718e-14 (R) and 4.721701e-14 (Python): R computes the p-value as 1 minus the chi-square distribution function, which loses digits this far into the tail; both are below 0.0005. The reading:
- Lags 1 to 3. Positive and outside the band: growth one to three quarters apart is positively correlated in this sample.
- Lags 4 to 8. Inside the band, none larger in size than 0.042.
- All eight together. \(Q(8) = 80.08\) rejects the null that they are all zero.
- The shape. A decline, the pattern of an autoregression. A stationary AR(1) has \(\rho(2) = \rho(1)^2\), and here \(r(2) = 0.416\) is above \(r(1)^2 = 0.309\), a slower decline than that.
- The cut-off. Under Bartlett's band too the bars stop after lag 3 (Figure 1), the pattern of an MA(3). An AR(1), an AR(2), an ARMA(1,1) and an MA(3) are all candidates, and the correlogram does not choose between them.
6. After estimation: residual correlograms
Once a model is fitted, the same tools check what dependence it has left behind: if a model describes the dependence fully, its errors are white noise and its residuals should show no autocorrelation beyond sampling variation. Figure 2 shows the residual correlograms of three models of GDP growth fitted by OLS: a constant only, whose residuals are growth minus its mean; an AR(1), growth on a constant and last quarter's growth; and an AR(2), with two lags.
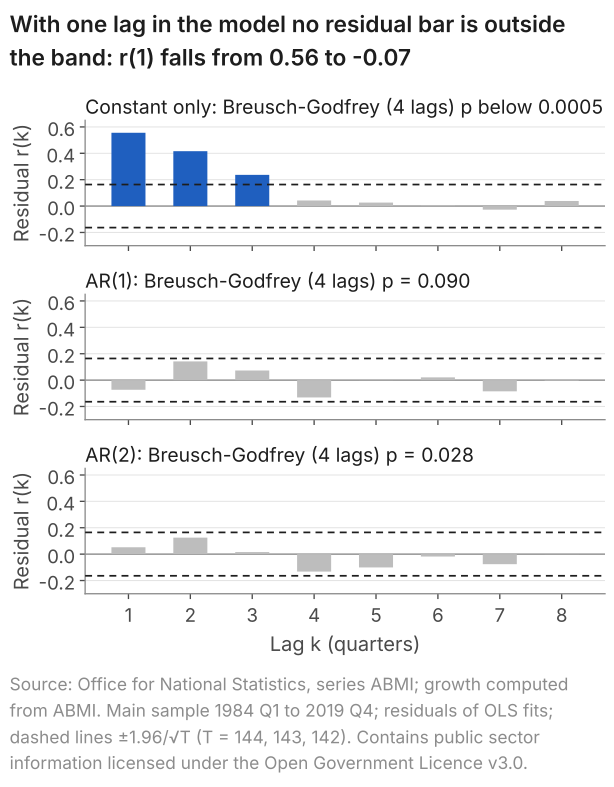
The Q-test on residuals needs one change. OLS makes the residuals uncorrelated in the sample with each lag in the model, which pulls the first residual autocorrelations towards zero even when the model is right. So \(Q\) on residuals is smaller on average than a \(\chi^2_m\) variable, and it is compared with \(\chi^2\) on \(m - p - q\) degrees of freedom, \(p\) and \(q\) counting the autoregressive and moving-average terms (not the constant).
| Model | Q(8) | Degrees of freedom | p-value |
|---|---|---|---|
| Constant only | 80.08 | 8 | below 0.0005 |
| AR(1) | 8.28 | 7 | 0.309 |
| AR(2) | 7.75 | 6 | 0.257 |
Degrees of freedom \(8 - p\), with \(p\) the number of AR terms; 5% critical values 15.51, 14.07 and 12.59.
The constant leaves strong autocorrelation in the residuals. The AR(1) leaves no bar outside the band at lags 1 to 8, and its \(Q(8)\), with p = 0.309, gives no evidence of autocorrelation in the residuals up to lag 8 at the 5% level. The AR(2) gives the same verdict, p = 0.257. Neither result shows that the residuals are white noise or that the model is right.
The Breusch-Godfrey test, a regression of the residuals on the model's regressors and on their own first four lags, gives a less tidy answer: p = 0.090 for the AR(1) and 0.028 for the AR(2) (the serial-correlation page). With p-values from 0.028 to 0.309 depending on the model and the test, whether a little dependence remains at these lags is borderline, and adding a second lag of growth does not settle it. Looking further out changes the picture: the AR(1)'s residual autocorrelations at lags 11 and 12 are 0.25 and -0.20, outside the band, and \(Q(12)\) rejects for both models (p = 0.003 and 0.009). The Q-test and the Breusch-Godfrey test both look for autocorrelation of autoregressive or moving-average form alike.
7. From a correlogram to a model
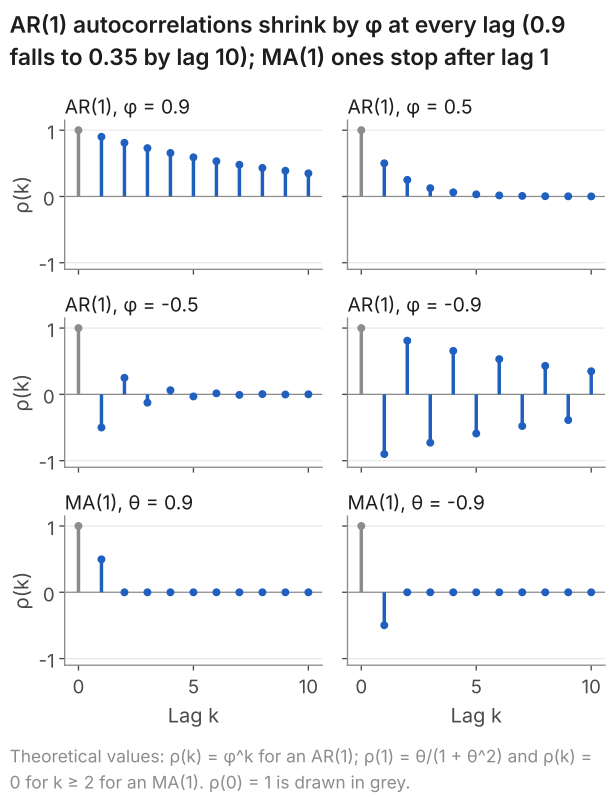
Setting a sample correlogram beside the autocorrelations that simple models imply gives a short list of candidates. For a stationary AR(1), \(Y_t = \alpha + \phi Y_{t-1} + \varepsilon_t\) with \(|\phi| < 1\) and white-noise shocks \(\varepsilon_t\), \(\rho(k) = \phi^k\): each autocorrelation is \(\phi\) times the one before, alternating in sign when \(\phi < 0\). For an MA(1), \(Y_t = \alpha + \varepsilon_t + \theta\,\varepsilon_{t-1}\), \(\rho(1) = \theta/(1+\theta^2)\) and every autocorrelation from lag 2 on is zero, since values two or more periods apart share no shock. Figure 3 shows both.
| Shape | What it suggests | Read more |
|---|---|---|
| Geometric decline | An AR(1): each bar a roughly constant fraction of the one before, alternating in sign if \(\phi < 0\). An irregular decline points to a higher-order AR or an ARMA. | AR(1), ARMA(1,1) |
| Cut-off after lag \(q\) | An MA(\(q\)): bars outside Bartlett's band up to lag \(q\), none after it. | MA(q) |
| Seasonal spikes | A seasonal pattern left in the series: spikes at lags 4, 8, ... in quarterly data, 12, 24 in monthly data. | Seasonality |
| Slow, near-linear decline | Bars close to 1 that fall slowly: a wandering level, such as a random walk. Difference the series first. | Random walks, differences |
| Nothing outside the band | Consistent with white noise, if the Q-test does not reject either. | White noise |
Each row is a suggestion, not an identification, because sample autocorrelations are noisy. In 100 values simulated from an MA(1) with \(\theta = 0.9\), \(r(1)\) is 0.59 against \(\rho(1) = 0.50\), and the bars at lags 6 and 7 fall outside the band of \(\pm 0.196\) although \(\rho(k) = 0\) there (the MA(1) paths); in 100 values of an ARMA(1,1) with \(\phi = 0.9\) and \(\theta = -0.6\), \(r(1)\) is 0.59 against 0.49. Candidates are then estimated, checked on their residuals (section 6) and compared with information criteria.
8. The partial autocorrelation
The partial autocorrelation separates the dependence at lag \(k\) from the dependence the shorter lags pass on: in an AR(1), \(Y_t\) depends on \(Y_{t-2}\) only through \(Y_{t-1}\), yet \(\rho(2) = \phi^2\) is not zero. The partial autocorrelation at lag \(k\) is the coefficient on \(y_{t-k}\) in a regression of \(y_t\) on a constant and its first \(k\) lags. For an AR(\(p\)) it is zero beyond lag \(p\), where its sample values are approximately normal with mean 0 and variance \(1/T\) in a large sample, so the same band applies. For an MA(\(q\)) the roles swap: the autocorrelations stop after lag \(q\) and the partial autocorrelations decline.
| Lag k | 1 | 2 | 3 | 4 |
|---|---|---|---|---|
| Partial autocorrelation | 0.557 | 0.148 | -0.070 | -0.169 |
UK GDP growth, 1984 Q1 to 2019 Q4: regressions of growth on a constant and its first k lags. Band ±0.163.
Lag 1 is far outside the band, lags 2 and 3 inside and lag 4 narrowly outside. An AR(1) is the simplest candidate: when the partial autocorrelations after lag 1 are zero, each of the three estimates here falls outside the band about one time in twenty, so one of three narrowly outside is weak evidence. At lag 1 the regression estimates \(\rho(1)\) again: 0.557 against \(r(1) = 0.556\).
9. Common mistakes
- "The bar at lag 11 is significant." Name the test and the level: a bar outside the constant band is evidence against zero autocorrelation at that lag at the 5% level, if the observations are independent. And count the chances: with twelve bars, one outside is weak evidence.
- Reading a bar against the wrong band. Whether the autocorrelations stop at lag \(k\) is a question for Bartlett's band: for GDP growth, \(r(3) = 0.237\) is well outside the constant band, ±0.163, but only narrowly outside Bartlett's, ±0.229.
- Testing residuals on \(m\) degrees of freedom. \(Q(8)\) on the residuals of an AR(1) has 7 degrees of freedom, and on those of an AR(2), 6.
- "Q does not reject, so the residuals are white noise." For the AR(2), \(Q(8)\) has p = 0.257, yet the Breusch-Godfrey test with four lags rejects at the 5% level (p = 0.028).
- "The correlogram shows that the process is an AR(1)." A shape suggests candidates: the correlogram of GDP growth is also consistent with an AR(2), an ARMA(1,1) or an MA(3).
- "A p-value of 0.000 means the null has no chance of being true." A printed 0.000 is a p-value below 0.0005: the probability of so large a \(Q\) if the autocorrelations were all zero, not of the null being true.
10. Check your understanding
Five questions, marked on the page; every option has an explanation, including the wrong ones. (Without JavaScript the explanations are shown beneath each question.)
1. Figure 1 draws the correlogram of 144 quarters of UK GDP growth twice. At lag 3, r(3) = 0.237, the constant band is ±0.163 and Bartlett's band is ±0.229. Which null hypothesis does Bartlett's band at lag 3 test?
That is the null of the constant band, ±0.163. Bartlett's band leaves the autocorrelations at lags 1 and 2 free, which is why it is wider: 1 + 2 × (0.556² + 0.416²) = 1.964, and 1.96 × √(1.964/144) = 0.229.
A hypothesis is about the process, not the sample: r(3) = 0.237 is known once the data are in. The null concerns ρ(3) and the lags beyond it, and r(3) is the evidence used to test it.
Correct. Bartlett's band at lag k tests whether the process could be a moving average of order k - 1, an MA(2) here: zero autocorrelation from lag 3 on, whatever the first two are. r(3) = 0.237 is outside ±0.229, narrowly, so that null is rejected at the 5% level.
2. An AR(2) fitted by OLS to UK GDP growth leaves 142 residuals, and the Ljung-Box statistic on their first eight autocorrelations is Q(8) = 7.75. On how many degrees of freedom should it be compared with the chi-square distribution?
This subtracts the constant as well as the two lags. The constant does not count: the adjustment is for the AR and MA terms, which pull the residual autocorrelations towards zero, so it is 8 - 2 - 0 = 6.
Correct. m - p - q = 8 - 2 - 0 = 6. The 5% critical value on 6 degrees of freedom is 12.59, and 7.75 is below it (p = 0.257): no evidence of autocorrelation in the residuals up to lag 8.
This subtracts one for the model as a whole. Each estimated AR or MA coefficient uses up one degree of freedom, so an AR(2) loses two: 8 - 2 = 6.
Eight is right for a series observed directly. OLS makes the residuals uncorrelated in the sample with the two lags in the model, so Q on residuals is smaller on average, and the degrees of freedom fall to 8 - 2 = 6.
3. In 100 values simulated from one process, r(1) = -0.52, well outside the band ±0.196, and every bar from lag 2 to lag 10 lies inside the band. Which model does this shape suggest as a first candidate?
Correct. An MA(1) has ρ(1) = θ/(1 + θ²) and ρ(k) = 0 from lag 2 on, the shape described. The values were in fact simulated from an MA(1) with θ = -0.9, whose ρ(1) is -0.497: the sample r(1), -0.52, is close to it, not equal.
An AR(1) with φ = -0.52 would have ρ(2) = φ² = 0.27, outside ±0.196, and further bars alternating in sign. Its autocorrelations decline geometrically; they do not stop after lag 1.
-0.52 is more than two and a half times the band's half-width. When the observations are independent about one bar in twenty falls outside the band, and then close to it; a bar this far outside is strong evidence against zero autocorrelation at lag 1.
4. The correlogram of 144 observations shows twelve bars. Eleven are well inside the band ±0.163; the bar at lag 11 is narrowly outside it. Which reading is justified?
A single bar narrowly outside is weak evidence. In 10,000 simulated series of 144 independent observations, 40.3% had at least one of their twelve bars outside the band, though no lag had any dependence.
Correct. With independent observations each bar falls outside the band with probability a little under 0.05, and twelve bars give twelve chances: in 10,000 simulated series of 144, at least one bar was outside in 40.3%. A joint test such as Q(12) answers the question for the twelve lags together.
A bar inside the band means no evidence against zero autocorrelation at that lag, not proof of it, and white noise is a claim about every lag. Not rejecting does not show that the null is true.
5. For the AR(1) fitted by OLS to 143 quarters of UK GDP growth, the Ljung-Box statistic on the residuals is Q(8) = 8.28 on 7 degrees of freedom, with p = 0.309. Which conclusion does this support at the 5% level?
Not rejecting is not a proof. The test looks at lags 1 to 8 only, and the Breusch-Godfrey test on the same residuals, with four lags, gives p = 0.090: weak evidence, not none. Neither shows that the model is right.
0.309 is the probability of a Q of 8.28 or more if the first eight residual autocorrelations are zero. The probability that they are zero would also need how plausible that was before the data, which a p-value does not use.
Correct. 8.28 is below the 5% critical value on 7 degrees of freedom, 14.07, so the null that the first eight residual autocorrelations are zero is not rejected. That is all the result says.
11. Questions about correlograms
A correlogram is a plot of a series' sample autocorrelations r(k) against the lag k, with a band around zero, here ±1.96/√T. For 144 quarters of UK GDP growth the band is ±0.163, and r(1) to r(3), 0.556, 0.416 and 0.237, lie outside it: growth one to three quarters apart is positively correlated in that sample.
Compare each bar, the sample autocorrelation at its lag, with the band. If the observations are independent, a bar outside ±1.96/√T (±0.163 for 144 quarters) is evidence against zero autocorrelation at that lag at the 5% level. Then read the shape: a steady decline suggests an autoregression, a cut-off after lag q a moving average of order q.
The Ljung-Box test checks whether the first m autocorrelations are all zero. Its statistic Q, a weighted sum of the squared autocorrelations times T, is approximately chi-square on m degrees of freedom for independent observations (m - p - q on ARMA residuals). For UK GDP growth Q(8) = 80.08, far above the 5% critical value, 15.51.
The ACF is the correlation between a series and its value k periods earlier; the PACF is the coefficient on that value when the series is regressed on its first k lags. An AR(p) has a PACF of zero after lag p, an MA(q) an ACF of zero after lag q. UK GDP growth: 0.416 against 0.148 at lag 2.
12. Where next
- The course lesson that teaches the idea slowly: lesson 23, autocorrelation and the correlogram, with \(r(1)\) worked by hand and a look at how much data \(r(k)\) needs.
- Autocorrelation and serial correlation: the Breusch-Godfrey and Durbin-Watson tests, and what serially correlated errors do to a regression.
- AR, MA, ARMA and ARIMA models: where the shapes of section 7 come from.
- Time series econometrics notes: process and realisation, stationarity, white noise and the autocorrelation function.
- ARMA estimation and model selection, and the module notes on the sample autocorrelation and the Q-test, for the algebra.
A correlogram or a Q-test you cannot read? Send it
I tutor econometrics one-to-one, from a first correlogram through to ARMA models, forecasting and the rest of time series. Bring the output you are stuck on and we will work through it in the free 30-minute consultation.
Book a free 30-minute consultation Econometrics tutor: how it works
Data and simulation. UK GDP growth: Source: Office for National Statistics, series ABMI (real GDP, chained volume measures, seasonally adjusted, quarterly; as published in September 2026, retrieved 10 October 2026); growth computed from ABMI. Contains public sector information licensed under the Open Government Licence v3.0. The file the code reads is uk-gdp-growth.csv. The partial autocorrelations of section 8 were computed for this page from the same 144 quarters. Figure 3 shows theoretical values; no simulation. Section 4's simulation: independent N(0, 1) values, 10,000 series of T = 144, numpy default_rng(2026) and standard_normal((10000, 144)), one row per series. Section 7's simulated examples: a fresh numpy default_rng(2026) and eps = rng.standard_normal(101) (shocks e(0) to e(100)); MA(1): Y(t) = e(t) + θ e(t-1), t = 1 to 100, with θ = 0.9 (section 7) and θ = -0.9 (question 3); ARMA(1,1): Y(t) = 0.9 Y(t-1) + e(t) - 0.6 e(t-1), t = 1 to 100, started at Y(0) = e(0), from the same shocks. Adapted from my lecture notes for Time Series Econometrics (ECON30401) at the University of Manchester.