
A series has memory when its value today depends on past values or past shocks: for UK GDP growth over 1984 to 2019, the sample autocorrelation between neighbouring quarters is 0.56. A model of such a series needs a rule for how long a shock lasts, and with what weight. MA, AR and ARMA models are such rules.
1. MA(1): today's shock plus a share of yesterday's
The MA(1) has the shortest memory in the family: each shock enters two values. A shock of size 1 at date \(t\) raises \(Y_t\) by 1 and \(Y_{t+1}\) by \(\theta\), and leaves every later value unchanged:
$$ Y_t = \alpha + \varepsilon_t + \theta\,\varepsilon_{t-1} . $$In words: today's value = a constant + today's shock + \(\theta\) times yesterday's shock.
The shocks \(\varepsilon_t\) are white noise: mean zero, variance \(\sigma^2\) at every date, no correlation between dates. So \(\alpha\) is the mean of \(Y_t\), in the units of the series, and \(\theta\) is a pure number. Were \(Y_t\) GDP growth, \(\varepsilon_t\) would be the shock to growth in quarter \(t\), felt that quarter and the next. The name refers to the right-hand side, a moving weighted sum of shocks.
Definition: MA(1) process
\(Y_t = \alpha + \varepsilon_t + \theta\,\varepsilon_{t-1}\) at every date, with \(\alpha\) and \(\theta\) fixed and \(\varepsilon_t\) white noise of variance \(\sigma^2\), written \(\varepsilon_t \sim \text{WN}(\sigma^2)\).
Remarks. Intuitively, neighbours share a shock and values two or more periods apart share none. An MA model is not a moving average of the data: it adds up shocks, which are never observed.
Figure 1 feeds one set of simulated shocks through four values of \(\theta\), and sets each path's sample autocorrelation at lag 1, r(1), beside the process's own value, \(\rho(1)\).
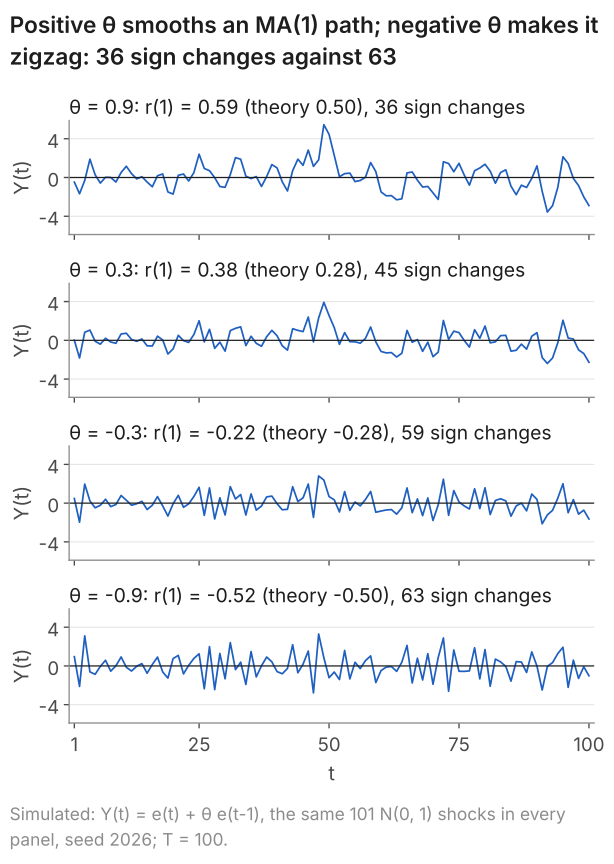
With \(\theta = 0.9\) neighbours share \(\varepsilon_{t-1}\) with positive weights and move together; with \(\theta = -0.9\) the weights have opposite signs and neighbours pull apart: 36 changes of sign against 63. Each r(1) is an estimate from 100 values. Books and software use other letters, such as \(\hat\rho(k)\) for r(k) or \(\eta\) for \(\theta\), and some put a minus sign in front of \(\theta\); the choice is cosmetic, but check the sign before comparing estimates.
What students say
“Nicky is an excellent econometrics tutor. He explains complex concepts clearly and makes them much easier to understand.”
“I was completely lost in my economics class, and then I started working Nicky and he totally saved me. He was excellent at explaining the material and extremely accommodating to meet with me many times despite us being in different time zones! Highly recommend working with Nicky!”
“Nicky is a very good and thorough teacher. He has excellent knowledge of econometrics and takes the time to work through your questions. Highly recommended!”
“Really great tutor! Encouraging, knowledgeable, friendly”
“Very good lesson, Nicky is very helpful.”
“Very helpful and clear.”
“I gather it was very useful, thank you!”
“Fantastic!”
2. Mean, variance and autocorrelation of an MA(1)
These properties say where an MA(1) centres, how far it spreads, and how strongly values at different dates move together. Write \(\gamma(k) = \operatorname{Cov}(Y_t, Y_{t-k})\) for the autocovariance at lag \(k\); \(\gamma(0)\) is the variance. If the shocks are white noise,
$$ \begin{aligned} E(Y_t) &= \alpha , \\ \gamma(0) &= \sigma^2(1+\theta^2) , \\ \gamma(1) &= \theta\,\sigma^2 , \\ \gamma(k) &= 0 \ \text{ for } k \ge 2 , \end{aligned} $$and dividing by the variance gives the autocorrelations \(\rho(k) = \gamma(k)/\gamma(0)\), which the bars of a correlogram estimate:
$$ \begin{aligned} \rho(1) &= \frac{\theta}{1+\theta^2} , \\ \rho(k) &= 0 \ \text{ for } k \ge 2 . \end{aligned} $$In words: the lag-1 autocorrelation is \(\theta\) over one plus \(\theta\) squared, and every later one is zero.
The numerator is the covariance made by the one shock that \(Y_t\) and \(Y_{t-1}\) share, \(\varepsilon_{t-1}\), and values further apart share none; the denominator adds the variances of the two shocks in \(Y_t\), \(\sigma^2\) and \(\theta^2\sigma^2\). The \(\sigma^2\) cancels, so \(\rho(1)\) has no units, while the variance is in squared units of the series. With \(\theta = 0.9\), \(\rho(1) = 0.9/1.81 = 0.50\), and no \(\theta\) gives more than 0.5 in size: the maximum is at \(\theta = \pm 1\).
Show the derivation of the MA(1) moments
White noise gives \(E(\varepsilon_t) = 0\), \(E(\varepsilon_t^2) = \sigma^2\), and \(E(\varepsilon_t \varepsilon_s) = 0\) for \(t \neq s\).
- Mean. Take expectations term by term: $$ \begin{aligned} E(Y_t) &= \alpha + E(\varepsilon_t) \\ &\qquad + \theta E(\varepsilon_{t-1}) = \alpha . \end{aligned} $$
- Variance. Square the deviation from the mean: $$ \begin{aligned} \gamma(0) &= E\big[(\varepsilon_t + \theta\varepsilon_{t-1})^2\big] \\ &= \sigma^2 + 2\theta E(\varepsilon_t\varepsilon_{t-1}) \\ &\qquad + \theta^2\sigma^2 \\ &= \sigma^2(1+\theta^2) . \end{aligned} $$
- Lag 1. Multiply the deviations at \(t\) and \(t-1\): $$ \begin{aligned} \gamma(1) &= E\big[(\varepsilon_t + \theta\varepsilon_{t-1}) \\ &\qquad \times (\varepsilon_{t-1} + \theta\varepsilon_{t-2})\big] \\ &= \theta\sigma^2 , \end{aligned} $$ since of the four products only \(\theta\varepsilon_{t-1} \times \varepsilon_{t-1}\) pairs a shock with itself.
- Lags 2 and beyond. \(Y_t\) contains \(\varepsilon_t, \varepsilon_{t-1}\) and \(Y_{t-k}\) contains \(\varepsilon_{t-k}, \varepsilon_{t-k-1}\): for \(k \ge 2\) no date is shared, so \(\gamma(k) = 0\).
- Divide. $$ \begin{aligned} \rho(1) &= \frac{\theta\sigma^2}{\sigma^2(1+\theta^2)} \\ &= \frac{\theta}{1+\theta^2} . \end{aligned} $$
- At most one half. \((1-|\theta|)^2 \ge 0\) gives \(1 + \theta^2 \ge 2|\theta|\), so \(|\rho(1)| \le 1/2\), with equality only at \(|\theta| = 1\).
The rules for the variance of a sum are in lesson 3; the module note has the same algebra.
3. MA(q): a memory of q periods
The MA(q) stretches the memory to \(q\) periods. A shock of size 1 at date \(t\) enters \(Y_t\) with weight 1, \(Y_{t+1}\) with \(\theta_1\), and so on to \(Y_{t+q}\) with \(\theta_q\); then it has gone:
$$ \begin{aligned} Y_t = {}& \alpha + \varepsilon_t + \theta_1\varepsilon_{t-1} \\ & + \dots + \theta_q\varepsilon_{t-q} . \end{aligned} $$In words: today's value = a constant + today's shock + a weighted sum of the last \(q\) shocks.
By the reasoning of section 2, values more than \(q\) periods apart share no shock, so \(\rho(k) = 0\) for every \(k > q\): the autocorrelations stop after lag \(q\). The mean is \(\alpha\), the variance \(\sigma^2(1 + \theta_1^2 + \dots + \theta_q^2)\) is finite, and nothing depends on \(t\), so an MA(q) is stationary for any \(\theta\)s (module note).
Overlapping data build this memory into real series. The ONS annual CPI inflation rate (series D7G7) compares each month's index with the index a year earlier; in logs, that is exactly the sum of the last twelve monthly changes, so two rates a month apart share eleven of them. Were the monthly changes white noise, the annual change in logs would be an MA(11) with every \(\theta\) equal to 1 and \(\rho(k) = (12-k)/12\): 0.92 at lag 1, zero from lag 12.
4. AR(1): every past shock, with fading weight
The AR(1) gives a shock a memory that never ends but fades. A shock of size 1 at date \(t\) raises \(Y_t\) by 1; \(Y_{t+1}\) is built from \(Y_t\) and carries \(\phi\) of it, \(Y_{t+2}\) carries \(\phi^2\), and so on, the weight shrinking each period when \(|\phi| < 1\). The rule is
$$ Y_t = \alpha + \phi\,Y_{t-1} + \varepsilon_t . $$In words: today's value = a constant + \(\phi\) times yesterday's value + today's shock.
Substituting the rule for \(Y_{t-1}\) shows where the weights come from:
$$ \begin{aligned} Y_t = {}& \alpha(1+\phi) + \phi^2 Y_{t-2} \\ & + \varepsilon_t + \phi\,\varepsilon_{t-1} , \end{aligned} $$and repeating it, the shock from \(j\) periods back arrives with weight \(\phi^j\). An AR(1) is a random fluctuation around a first-order difference equation, \(Y_t = \alpha + \phi\,Y_{t-1}\): the equation sets the dynamics and the shocks supply the randomness. \(Y_t\) is regressed on its own past value, hence auto-regressive: the AR(1) is the model, and OLS one method of estimating it (section 9).
Figure 2 feeds one set of 100 simulated shocks through four values of \(\phi\), each path starting at the process mean, \(Y_0 = 0\).
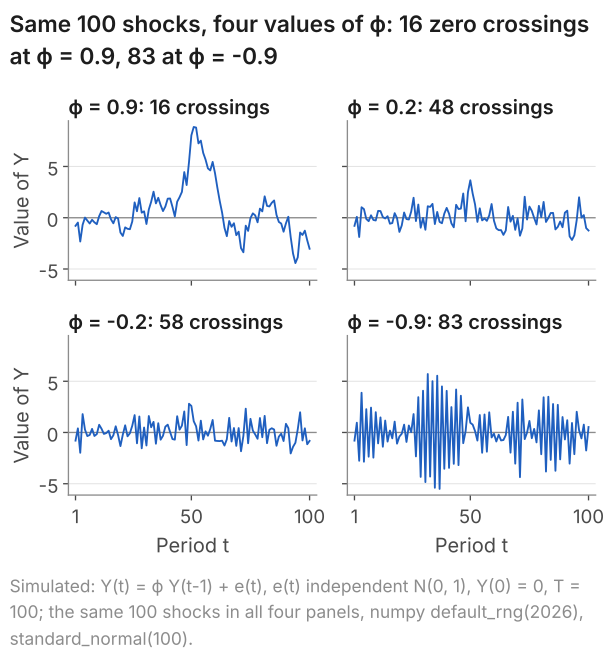
With \(\phi = 0.9\) a shock keeps \(0.9^{10} = 0.35\) of its weight ten periods on, so shocks pile up into long swings; with \(\phi = -0.9\) the weight alternates in sign, and neighbours have opposite signs in 83 of the 99 steps. The AR(1) fitted by OLS to UK GDP growth over 1984 Q1 to 2015 Q4 lies between the top two panels: in that fitted rule, with \(\hat\phi = 0.56\), a shock keeps 56% of its size one quarter on and 32% two quarters on. Lesson 25 builds the AR(1) slowly.
5. AR(1): stationarity and autocorrelations
Whether the fading memory settles into a stable process depends on \(\phi\).
Definition: stationary AR(1)
The AR(1) with white-noise shocks of variance \(\sigma^2\) is stationary when \(|\phi| < 1\) and it has run from the distant past, or starts from its stationary distribution. It then has mean \(\mu\), variance \(\gamma(0)\) and autocorrelations \(\rho(k)\):
$$ \begin{aligned} \mu &= \frac{\alpha}{1-\phi} , \\ \gamma(0) &= \frac{\sigma^2}{1-\phi^2} , \\ \rho(k) &= \phi^k \ \ (k \ge 1) . \end{aligned} $$Remarks. Intuitively, old shocks fade, so the distribution of \(Y_t\) stops depending on the date. The mean is \(\alpha/(1-\phi)\), not \(\alpha\).
In words: the mean is the intercept over one minus \(\phi\), the variance the shock variance over one minus \(\phi\) squared, and the lag-\(k\) autocorrelation \(\phi\) to the power \(k\).
Stationarity gives each in one line. Equal means at \(t\) and \(t-1\) turn the rule into \(\mu = \alpha + \phi\mu\): with \(\alpha = 0.25\) and \(\phi = 0.5\), \(\mu = 0.5\). \(Y_{t-1}\) is built from earlier shocks, uncorrelated with \(\varepsilon_t\), so equal variances give \(\gamma(0) = \phi^2\gamma(0) + \sigma^2\): \(1.33\sigma^2\) at \(\phi = 0.5\), \(5.26\sigma^2\) at \(\phi = 0.9\), in squared units of the series. And \(Y_t\) is \(\phi^k Y_{t-k}\) plus a constant and later shocks, uncorrelated with \(Y_{t-k}\), so \(\rho(k) = \phi^k\). Lesson 25 derives the mean step by step. Figure 3 draws these autocorrelations beside those of two MA(1)s.
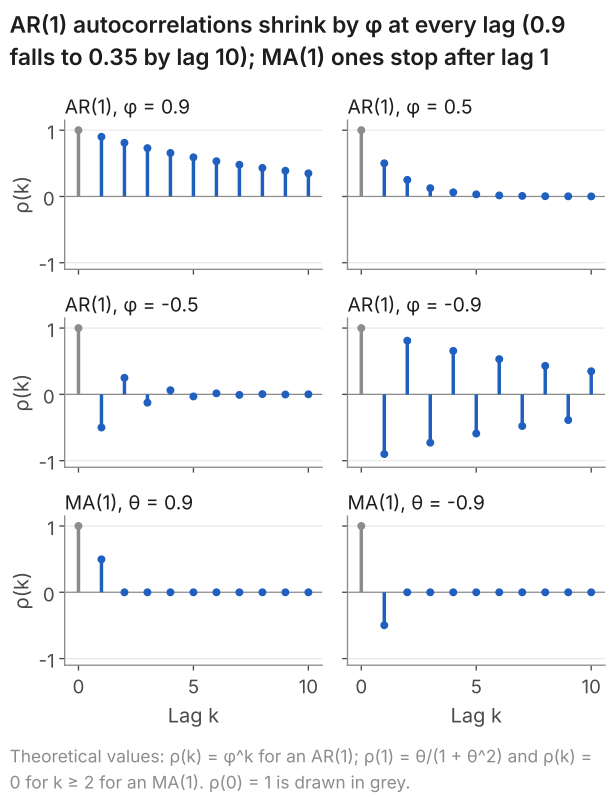
Outside \(|\phi| < 1\) the memory does not fade. With \(\phi = 1\) every shock stays at full weight: \(Y_t = Y_{t-1} + \varepsilon_t\) is the random walk, and \(\phi = 1\) is called a unit root. From \(Y_0 = 0\) it is the sum of the first \(t\) shocks, so its variance \(t\sigma^2\) is finite at each date but grows without limit: the process is not stationary. Fed the shocks of Figure 2, it stands at 10.85 at \(t = 50\), where its standard deviation is \(\sqrt{50} = 7.07\). With \(|\phi| > 1\) the weights grow and the process is explosive: at \(\phi = 1.1\) a shock 50 periods back carries weight \(1.1^{50} = 117\), and the same shocks reach -7,969.8 at \(t = 100\).
6. ARMA(1,1): both kinds of memory
The ARMA(1,1) puts the two mechanisms in one rule. A shock of size 1 at date \(t\) raises \(Y_t\) by 1 and \(Y_{t+1}\) by \(\phi + \theta\), through yesterday's value and yesterday's shock; after that only the AR part carries it, and its weight shrinks by the factor \(\phi\) each period:
$$ Y_t = \alpha + \phi\,Y_{t-1} + \varepsilon_t + \theta\,\varepsilon_{t-1} . $$In words: today's value = a constant + \(\phi\) times yesterday's value + today's shock + \(\theta\) times yesterday's shock.
With \(\theta = 0\) it is an AR(1), and with \(\phi = 0\) an MA(1). The MA term adds one shock with a finite weight, so the process is stationary under the AR(1)'s condition, \(|\phi| < 1\), with mean \(\alpha/(1-\phi)\). From lag 2 on only the AR part links two values, so each autocorrelation is \(\phi\) times the one before; \(\rho(1)\) depends on \(\theta\) as well, since \(Y_t\) and \(Y_{t-1}\) share the shock \(\varepsilon_{t-1}\) (module note).
When \(\theta = -\phi\) the two parts cancel: a shock moves \(Y_{t+1}\) by \(\phi + \theta = 0\) and every later value by a multiple of that zero, so the process is its mean plus white noise. With \(\alpha = 0\), \(\phi = 0.6\), \(\theta = -0.6\) and \(Y_0 = \varepsilon_0\), the rule gives \(Y_1 = 0.6\,\varepsilon_0 + \varepsilon_1 - 0.6\,\varepsilon_0 = \varepsilon_1\), and so on: the path is exactly the shocks. From another start, \(Y_t - \varepsilon_t\) is \(0.6^t\) times its starting value, halving about every 1.4 periods. Figure 4 shows it last.
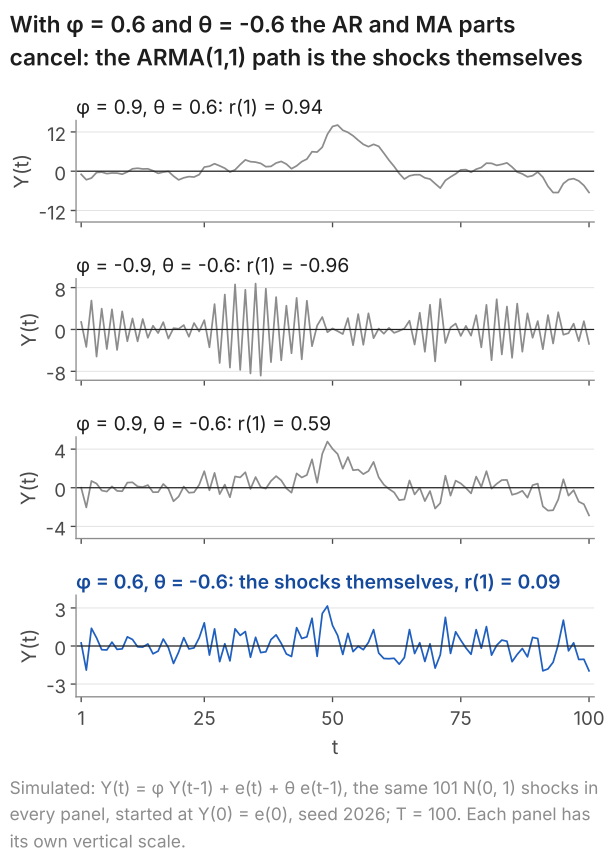
In the third panel, \(\theta = -0.6\) takes back two thirds of the AR effect one period on, leaving \(\phi + \theta = 0.3\), and the rest fades at the rate 0.9: a modest \(\rho(1)\), then a slow decline. An AR(1) has \(\rho(2) = \rho(1)^2\), so no AR(1) has that shape. The sample autocorrelations of UK GDP growth also fall more slowly from lag 1 to lag 2 than an AR(1)'s do: over 1984 Q1 to 2019 Q4 the sample values at lags 1 and 2 are 0.556 and 0.416, while an AR(1) with \(\rho(1) = 0.556\) has \(\rho(2) = 0.556^2 = 0.309\). An AR(1) is one candidate for the series; an ARMA(1,1) or an AR(2) are others, compared by estimating and checking each (section 8).
7. AR(p) and ARMA(p,q)
More lags give more freedom to shape the memory. In an AR(p) a shock reaches later values through each of the last \(p\) values, so its weights can die away smoothly, alternate in sign, or swing in damped cycles; an ARMA(p,q) adds \(q\) lagged shocks, which reshape the first \(q\) weights:
$$ \begin{aligned} Y_t = {}& \alpha + \phi_1 Y_{t-1} + \dots + \phi_p Y_{t-p} \\ & + \varepsilon_t + \theta_1 \varepsilon_{t-1} \\ & + \dots + \theta_q \varepsilon_{t-q} . \end{aligned} $$In words: \(p\) lagged values and \(q\) lagged shocks; with \(q = 0\), the AR(p).
The MA part is a finite sum of shocks, so stationarity depends on the AR part alone: every root \(z\) of \(1 - \phi_1 z - \dots - \phi_p z^p = 0\) must satisfy \(|z| > 1\), which for \(p = 1\) is \(|\phi| < 1\) (AR(p) stationarity, with the lag operator). An AR(p)'s autocorrelations die away; its order shows in the partial autocorrelations, which are zero beyond lag \(p\).
8. ARIMA models and the Box-Jenkins method
An ARIMA model handles a series with no fixed mean to return to, such as the level of log real GDP, by modelling its changes. An ARIMA(p, d, q) says that the series, differenced \(d\) times, follows an ARMA(p, q); the I stands for integrated, the name for a series that becomes stationary after differencing. A random walk is an ARIMA(0, 1, 0), since its first difference is white noise (lesson 24). Differencing a series that is already stationary adds memory it did not have: white noise becomes an MA(1) with \(\theta = -1\) and \(\rho(1) = -0.5\). The Box-Jenkins method builds a model in three steps, repeated until the last passes: identify \(d\), \(p\) and \(q\) from the correlograms of the series and its differences (from a correlogram to a model); estimate the model (estimation and model selection); check the residuals for leftover autocorrelation (the Breusch-Godfrey test).
9. An AR(1) for UK GDP growth
Estimating an AR(1) by OLS means regressing the series on its own value one period earlier. The series is UK GDP growth, quarter on quarter, in per cent, \(100 \times (\text{GDP}_t/\text{GDP}_{t-1} - 1)\), from ONS series ABMI as published in September 2026. The sample, 1984 Q1 to 2015 Q4, gives 128 quarters and 127 pairs; lesson 25 uses it and keeps 2016 to 2019 back to test forecasts. The quarters from 2020 are left out because two pandemic quarters dominate every statistic: adding the quarters to 2026 Q2 turns r(1) from 0.56 (1984 to 2019) to -0.27 (lesson 22).
| Term | Estimate | Std. error | t | p-value |
|---|---|---|---|---|
| Intercept, \(\hat\alpha\) | 0.25 | 0.065 | 3.79 | below 0.0005 |
| Last quarter's growth, \(\hat\phi\) | 0.56 | 0.074 | 7.60 | below 0.0005 |
127 pairs; residual standard error 0.56; R-squared 0.316; 95% interval for \(\phi\): 0.42 to 0.71.
The code reads uk-gdp-growth.csv (quarter, GDP, growth); download it from that link into your working folder first.
R: the code
# AR(1) for UK GDP growth: this quarter's growth on last quarter's, 1984 Q1 to 2015 Q4
gdp <- read.csv("uk-gdp-growth.csv")
# full-precision growth from gdp (the file's growth column has 4 decimals)
gdp$growth <- c(NA, 100 * (gdp$gdp[-1] / head(gdp$gdp, -1) - 1))
d <- subset(gdp, quarter >= "1984Q1" & quarter <= "2015Q4")
d$lag_growth <- c(NA, head(d$growth, -1))  # last quarter's growth (none for 1984 Q1)
fit <- lm(growth ~ lag_growth, data = d)
summary(fit)
confint(fit)
R: what it prints
> # AR(1) for UK GDP growth: this quarter's growth on last quarter's, 1984 Q1 to 2015 Q4
> gdp <- read.csv("uk-gdp-growth.csv")
> # full-precision growth from gdp (the file's growth column has 4 decimals)
> gdp$growth <- c(NA, 100 * (gdp$gdp[-1] / head(gdp$gdp, -1) - 1))
> d <- subset(gdp, quarter >= "1984Q1" & quarter <= "2015Q4")
> d$lag_growth <- c(NA, head(d$growth, -1))  # last quarter's growth (none for 1984 Q1)
> fit <- lm(growth ~ lag_growth, data = d)
> summary(fit)

Call:
lm(formula = growth ~ lag_growth, data = d)

Residuals:
     Min       1Q   Median       3Q      Max
-1.73038 -0.28122  0.00365  0.24271  1.41262

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept)  0.24624    0.06500   3.788 0.000235 ***
lag_growth   0.56163    0.07393   7.597 6.19e-12 ***
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1

Residual standard error: 0.5598 on 125 degrees of freedom
  (1 observation deleted due to missingness)
Multiple R-squared:  0.3159,	Adjusted R-squared:  0.3104
F-statistic: 57.72 on 1 and 125 DF,  p-value: 6.189e-12

> confint(fit)
                2.5 %    97.5 %
(Intercept) 0.1175900 0.3748824
lag_growth  0.4153178 0.7079375
Python: the code
import pandas as pd
import statsmodels.formula.api as smf

# AR(1) for UK GDP growth: this quarter's growth on last quarter's, 1984 Q1 to 2015 Q4
gdp = pd.read_csv("uk-gdp-growth.csv")
# full-precision growth from gdp (the file's growth column has 4 decimals)
gdp["growth"] = 100 * gdp["gdp"].pct_change()
d = gdp[gdp["quarter"].between("1984Q1", "2015Q4")].copy()
d["lag_growth"] = d["growth"].shift(1)  # last quarter's growth (none for 1984 Q1)
fit = smf.ols("growth ~ lag_growth", data=d).fit()
print(fit.summary())
Python: what it prints
                            OLS Regression Results
==============================================================================
Dep. Variable:                 growth   R-squared:                       0.316
Model:                            OLS   Adj. R-squared:                  0.310
Method:                 Least Squares   F-statistic:                     57.72
Date:                Sat, 10 Oct 2026   Prob (F-statistic):           6.19e-12
Time:                        21:43:27   Log-Likelihood:                -105.51
No. Observations:                 127   AIC:                             215.0
Df Residuals:                     125   BIC:                             220.7
Df Model:                           1
Covariance Type:            nonrobust
==============================================================================
                 coef    std err          t      P>|t|      [0.025      0.975]
------------------------------------------------------------------------------
Intercept      0.2462      0.065      3.788      0.000       0.118       0.375
lag_growth     0.5616      0.074      7.597      0.000       0.415       0.708
==============================================================================
Omnibus:                       10.929   Durbin-Watson:                   2.068
Prob(Omnibus):                  0.004   Jarque-Bera (JB):               18.098
Skew:                          -0.380   Prob(JB):                     0.000118
Kurtosis:                       4.686   Cond. No.                         2.18
==============================================================================

Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.
In the fitted rule, a quarter of growth one percentage point above the mean is followed on average by one 0.56 points above it. The implied mean, in per cent a quarter, is $$ \frac{\hat\alpha}{1-\hat\phi} = \frac{0.2462}{1-0.5616} = 0.56 , $$ close to the sample mean of 0.57%. Python also prints a Durbin-Watson statistic, which a lagged dependent variable pulls towards 2, so it is not a valid test here (why); lesson 25 reads the rest of the output.
10. Summary: how each model remembers
The table sets the models side by side; throughout, \(\varepsilon_t\) is white noise, and each condition on the \(\phi\)s assumes the process has run from the distant past.
| Model | Rule for \(Y_t\) | Stationary when | How long a shock lasts | Autocorrelations |
|---|---|---|---|---|
| White noise | \(\varepsilon_t\) | Always | Its own period | Zero from lag 1 |
| MA(1) | \(\alpha + \varepsilon_t + \theta\varepsilon_{t-1}\) | Always | Two periods: weights 1, \(\theta\) | \(\theta/(1+\theta^2)\) at lag 1, then zero |
| MA(q) | \(\alpha + \varepsilon_t + \dots + \theta_q\varepsilon_{t-q}\) | Always | \(q + 1\) periods | Zero beyond lag \(q\) |
| AR(1) | \(\alpha + \phi Y_{t-1} + \varepsilon_t\) | \(|\phi| < 1\) | For ever, weight \(\phi^j\) after \(j\) periods | \(\phi^k\), alternating in sign if \(\phi < 0\) |
| Random walk | \(Y_{t-1} + \varepsilon_t\) | Never | For ever, at full weight | None that depend on the lag alone |
| ARMA(1,1) | \(\alpha + \phi Y_{t-1} + \varepsilon_t + \theta\varepsilon_{t-1}\) | \(|\phi| < 1\) | For ever unless \(\theta = -\phi\): \(\phi + \theta\), then times \(\phi\) each period | \(\phi\) times the one before, from lag 2 |
| AR(p), ARMA(p,q) | \(p\) lagged values, \(q\) lagged shocks | Every AR root has \(|z| > 1\) | For ever, weights set by the \(\phi\)s and \(\theta\)s | Die away, possibly in damped cycles |
| ARIMA(p,d,q) | ARMA(p,q) for the \(d\)-th difference | The \(d\)-th difference is; the series is not | As in the ARMA, for the differences | |
11. Common mistakes
- "The mean of an AR(1) is \(\alpha\)." For a stationary AR(1) it is \(\alpha/(1-\phi)\): for GDP growth in section 9 the intercept is 0.25 and the implied mean 0.56% a quarter.
- "\(\theta\) is the lag-1 autocorrelation of an MA(1)." It is \(\theta/(1+\theta^2)\), never above 0.5 in size: \(\theta = 0.9\) gives 0.50.
- "A random walk is explosive." Explosive means \(|\phi| > 1\). With \(\phi = 1\) the variance from a fixed start is \(t\sigma^2\), finite at every date but growing without limit: not stationary, yet not explosive.
- "An AR(p) is stationary if each \(\phi_j\) is below 1 in size." The condition is on the roots: the AR(2) with \(\phi_1 = 0.6\) and \(\phi_2 = 0.5\) has a root at \(z = 0.94\) and is not stationary.
12. Check your understanding
Five questions, marked on the page; every option has an explanation, including the wrong ones. (Without JavaScript the explanations are shown beneath each question.)
1. The top panel of Figure 1 is an MA(1) with θ = 0.9, and its 100 values give a sample autocorrelation r(1) = 0.59. What is the autocorrelation at lag 1 of the process, ρ(1)?
Correct. ρ(1) = θ/(1 + θ²) = 0.9/1.81 = 0.497, which rounds to 0.50. The sample value 0.59 differs from it because 100 values give an estimate; another 100 shocks would give another r(1).
0.59 is the number in the figure, but it is what this one path of 100 values gives, a sample autocorrelation. The process's ρ(1) comes from θ alone: 0.9/(1 + 0.81) = 0.50.
0.81 is θ², as if the covariance were θ²σ². Of the four products in the covariance only θε(t-1) times ε(t-1) pairs a shock with itself, so the covariance is θσ² and ρ(1) = 0.9/1.81 = 0.50.
θ itself tempts because an AR(1)'s lag-1 autocorrelation is its φ, but θ is only the weight on yesterday's shock. The autocorrelation divides the covariance θσ² by the variance (1 + θ²)σ², which gives 0.9/1.81 = 0.50; an MA(1) never has ρ(1) above 0.5 in size.
2. A stationary process has ρ(1) = -0.5, ρ(2) = 0.25, ρ(3) = -0.125, and so on: at every lag the autocorrelation is -0.5 times the one before. Which model has these autocorrelations?
The first autocorrelation, -0.5, invites θ = -0.5, but an MA(1)'s autocorrelations stop after lag 1: with θ = -0.5, ρ(1) = -0.5/1.25 = -0.4 and ρ(2) = 0. Autocorrelations that die away lag by lag point to an autoregression.
Reading the coefficients off the first two autocorrelations is tempting, but an AR(2) with these coefficients has ρ(1) = φ1/(1 - φ2) = -0.5/0.75 = -0.67, not -0.5: the coefficient on a lag is not the autocorrelation at that lag.
Correct. An AR(1) has ρ(k) = φk, so φ = -0.5 gives -0.5, 0.25, -0.125 and so on: each is -0.5 times the one before, and the signs alternate because φ is negative.
3. The AR(1) fitted by OLS to UK GDP growth over 1984 Q1 to 2019 Q4 (143 pairs) has intercept 0.2448 and slope 0.5572. What mean growth rate, in per cent a quarter, does the fitted rule imply?
0.2448 × (1 - 0.5572) = 0.11 multiplies by 1 - φ, as if persistence shrank the intercept. The mean solves μ = α + φμ, which divides instead: 0.2448/0.4428 = 0.55.
0.24 is the intercept, the first number in the output, and it equals the mean only when φ = 0. With φ = 0.5572 the mean solves μ = α + φμ, so μ = 0.2448/(1 - 0.5572) = 0.55.
0.2448/(1 - 0.5572²) = 0.36 borrows 1 - φ² from the variance, σ²/(1 - φ²), a formula with the same look. The mean has 1 - φ: 0.2448/0.4428 = 0.55.
Correct. For a stationary AR(1), μ = α/(1 - φ) = 0.2448/(1 - 0.5572) = 0.2448/0.4428 = 0.55% a quarter, close to the sample mean of these 144 quarters, 0.56%.
4. An ARMA(1,1), Y(t) = φY(t-1) + ε(t) + θε(t-1), has |φ| < 1 and no intercept, and has run from the distant past. For which values of φ and θ is the process white noise?
It seems that each part can only add memory, and both zero does give white noise, but it is not the only case. When θ = -φ a shock moves the next value by φ + θ = 0 and every later value by a multiple of that zero: the bottom panel of Figure 4, with φ = 0.6 and θ = -0.6.
Correct. A shock moves the next value by φ + θ and later values by φ + θ times powers of φ. With θ = -φ all of these are zero, so each shock affects only its own period and Y(t) = ε(t), as in the bottom panel of Figure 4.
Equal coefficients look as if they might cancel, but with θ = φ the weight one period on is φ + θ = 2φ, so the parts add up: φ = θ = 0.6 gives 1.2. Cancelling needs opposite signs, θ = -φ.
5. Log real GDP is modelled as an ARIMA(1, 1, 0). What does the middle number, d = 1, say about the model?
Correct. d is the number of times the series is differenced. With d = 1 the change in log real GDP (roughly the growth rate, divided by 100) follows an ARMA(1, 0), that is, an AR(1).
A 1 in the middle is easy to read as an MA order, but lagged shocks are counted by q, the last number, which is 0 here. The middle number counts differences: the change in the series follows the ARMA(1, 0).
A series that wanders can look as if it trends, but integrated does not mean a trend term. It means the series is modelled through its differences: here the first difference follows an AR(1).
13. Questions about AR, MA, ARMA and ARIMA models
An autoregressive (AR) model writes today's value of a series as a constant plus a weighted sum of its own past values plus a new random shock. In an AR(1) a shock's weight shrinks by the factor φ each period, provided φ lies between -1 and 1. For UK GDP growth, 1984 to 2015, OLS estimates φ at 0.56.
An MA model builds today's value from the current shock and a fixed number of past shocks, so a shock is forgotten after q periods and the autocorrelations stop after lag q. An AR model builds it from past values, so every past shock is carried forward with a weight that fades, and the autocorrelations die away gradually.
An ARMA(p, q) model puts p lagged values and q lagged shocks of a series into one equation. In the ARMA(1,1) a shock moves the next value by φ + θ, then its weight shrinks by the factor φ each period. When θ equals minus φ the two parts cancel and the process is white noise around its mean.
An ARIMA(p, d, q) model says that a series, once differenced d times, follows an ARMA(p, q) model; the I stands for integrated. A random walk is an ARIMA(0, 1, 0), because its first difference is white noise. The Box-Jenkins method chooses p, d and q from correlograms, estimates the model and then checks its residuals.
14. Where next
- Lesson 25: AR(1) models and forecasting, the slow version of sections 4, 5 and 9.
- Lesson 24: the random walk and its differences.
- How to read a correlogram, with the partial autocorrelation.
- Estimating AR and MA models and choosing their order.
- Time series notes, part 2: the Wold decomposition and the lag operator.
- The module notes on MA processes and AR and ARMA processes, with the algebra in full.
Stuck on an AR, MA or ARMA question? Send it
I tutor econometrics one-to-one, up to time series models and forecasting. Bring the question you are stuck on, with the module and the deadline, and we will work through it in the free 30-minute consultation.
Book a free 30-minute consultation Econometrics tutor: how it works
Data and simulation. UK GDP growth: Source: Office for National Statistics, series ABMI; growth computed from ABMI. Contains public sector information licensed under the Open Government Licence v3.0. ABMI as published in September 2026, retrieved 10 October 2026. Figures 1 and 4: a fresh numpy default_rng(2026), then standard_normal(101) for \(\varepsilon_0\) to \(\varepsilon_{100}\), the same shocks in every panel; Figure 4 starts at \(Y_0 = \varepsilon_0\). Figure 2: a fresh default_rng(2026), then standard_normal(100) for \(\varepsilon_1\) to \(\varepsilon_{100}\), with \(Y_0 = 0\); the random walk and the path with \(\phi = 1.1\) in section 5 use the same shocks and start. Adapted from my lecture notes for Time Series Econometrics (ECON30401) at the University of Manchester.